非常牛逼的部署方案和内存加载kv技术帮我解决了困扰许久的问题
-
我4天前发了一贴, 后发现有点问题,就删帖了。
这几天密集测试使用了一下,确实可用, 现在官方也支持rocm编译, 长上下文prefill会很慢,但能正常工作。
prefill 一路下跌
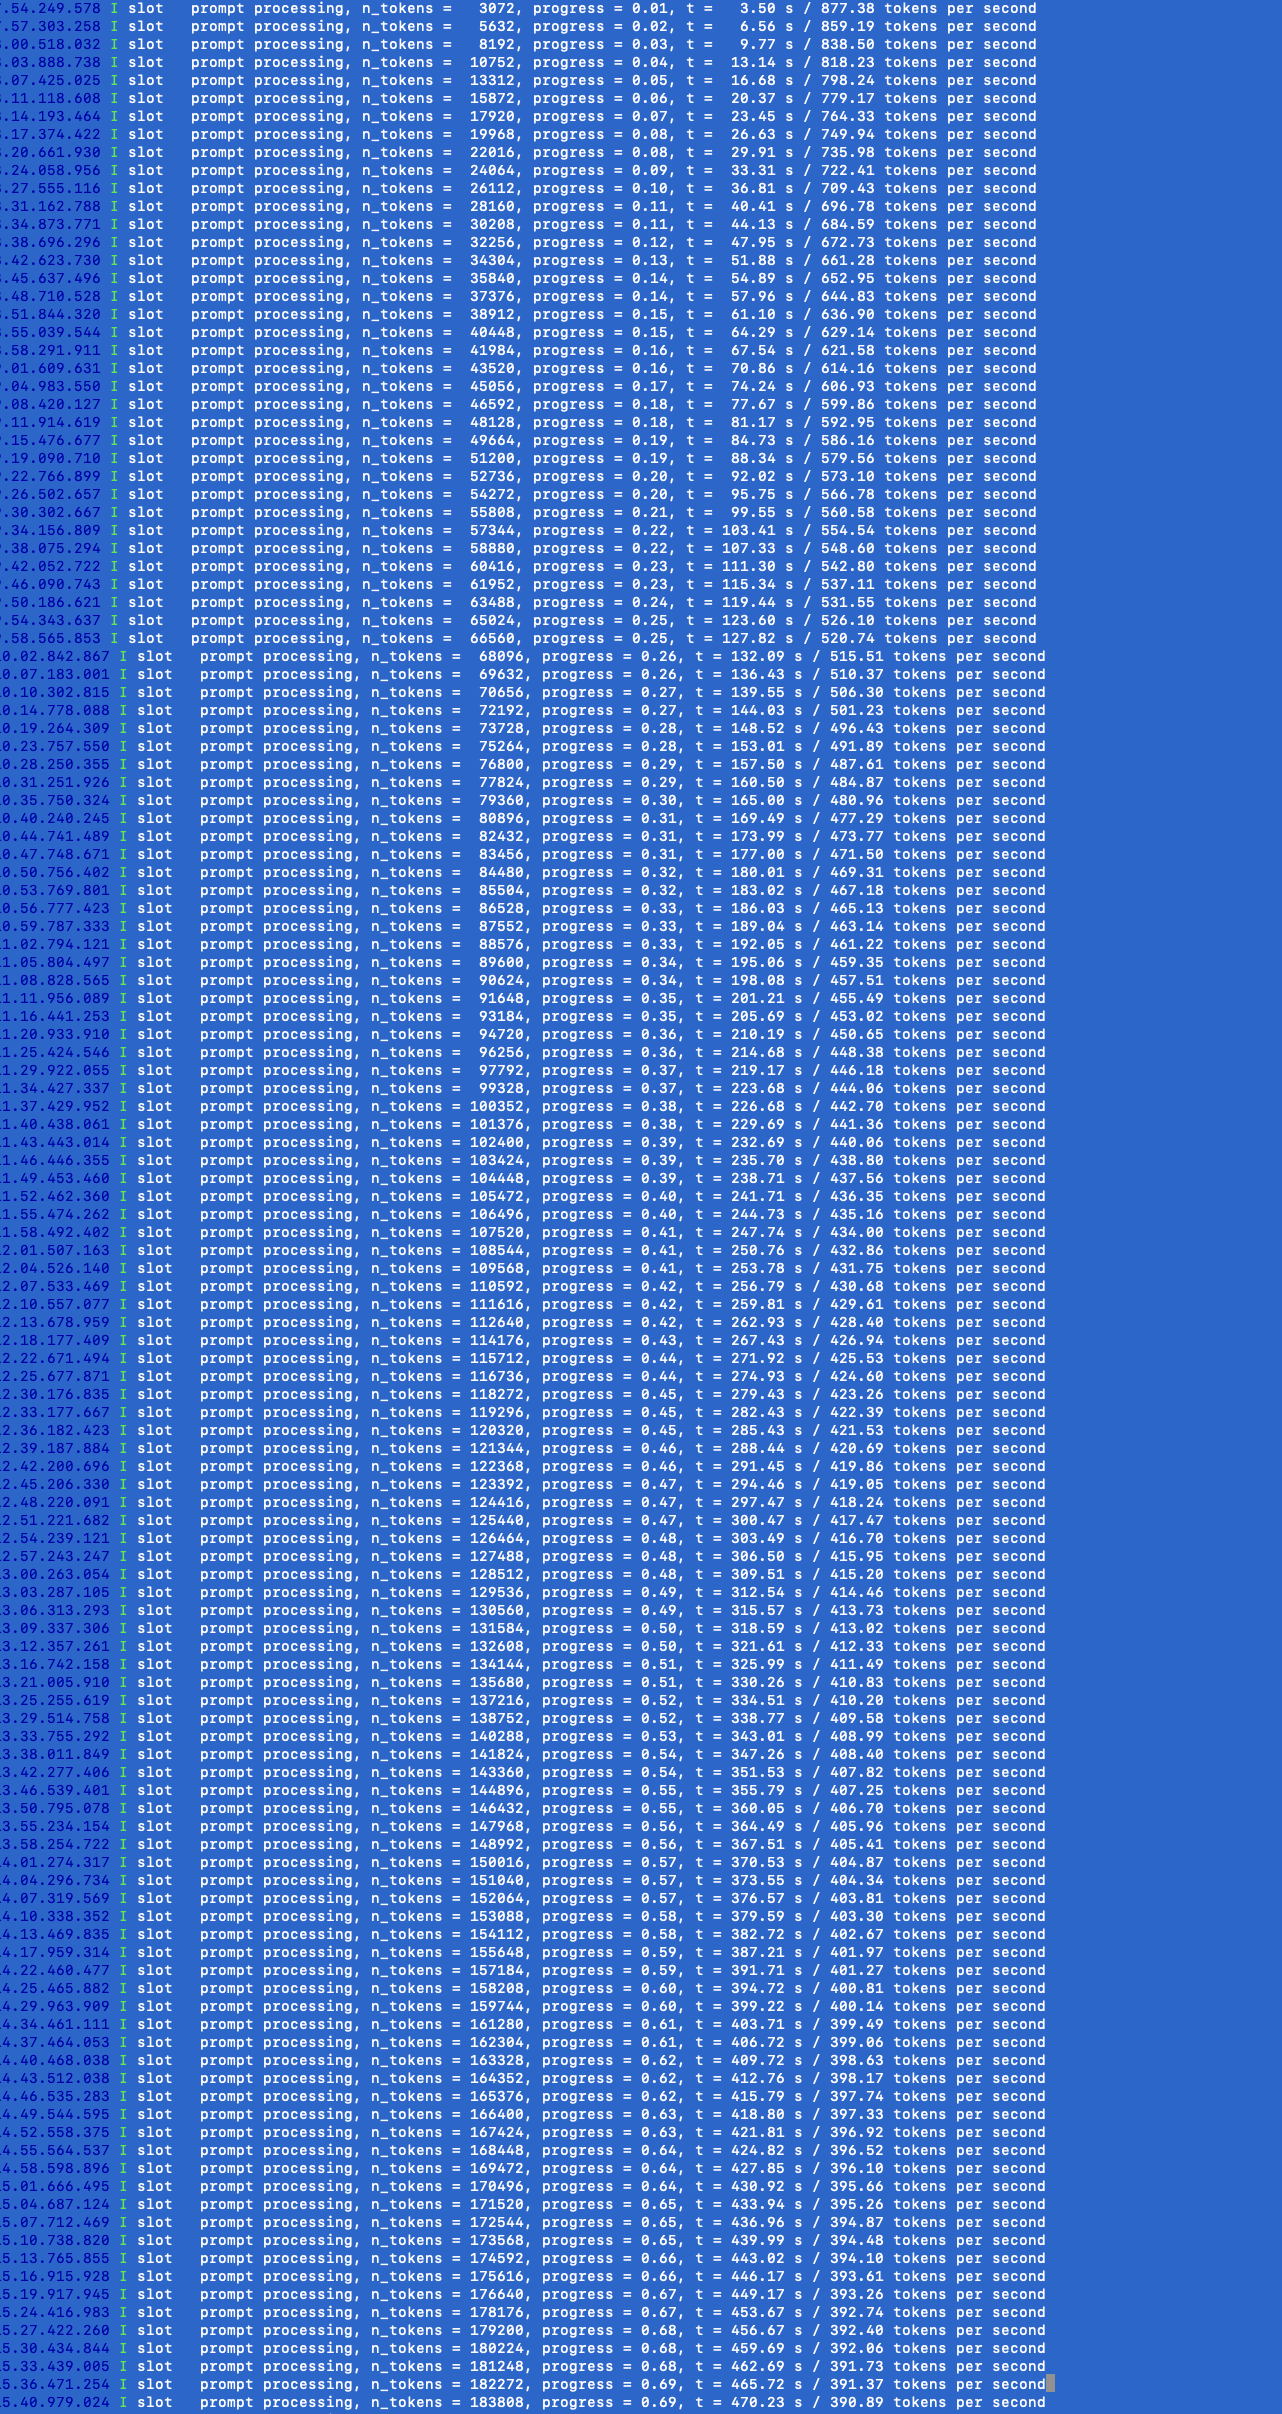
这是在7900xtx上512k上下文启动, 256k长上下文测试结果:
ctx (tokens) depth wall (s) prefill (tok/s) decode (tok/s) gen tokens finish answer hit 265085 1 777 373.7 30.1 5 stop 'AMBER-80' yes 启动参数:
./llama-kvmem-server -m /models/unsloth/Qwen3.8-27B-GGUF/Qwen3.8-27B-Q5_K_M.gguf --mmproj /models/unsloth/Qwen3.8-27B-GGUF/mmproj-BF16.gguf --host 0.0.0.0 --port 8080 --temp 0.7 --top-p 0.85 --top-k 20 --jinja --spec-type draft-mtp --kvmem --kvmem-budget 49152 --kvmem-gen-reserve 24576 --kvmem-gpu-ratio 0.85 --spec-draft-n-max 3 --reasoning-effort medium --ctx-size 524288 --reasoning-budget 4096 -n 32767测试脚本:
#!/usr/bin/env python3 """Long-context probe: does the server answer a question from deep in a huge prompt? Sends a "needle in a haystack" prompt of increasing size to a running llama-kvmem-server and checks that the model returns the phrase buried in the document. Prompt tokens are read back from the server's own `usage.prompt_tokens` (not estimated), so the requested size is the real prefill length even though the client has no tokenizer. The one required argument is the maximum prompt size in tokens: scripts/long_context_probe.py 131072 That runs probes at 1/4, 1/2, 3/4 and all of the maximum, plus position probes at the maximum (needle near the start, middle and end) to cover eviction/retrieval at both ends of the context. Exit status is 0 only if every probe returned the needle. Requires no third-party packages and never starts or stops a server. Server-side conditions this assumes (known from the running launch): - the server's -c is at least the requested maximum, and - the kvmem budget is smaller than the prompt, so eviction/retrieval is actually exercised. Check `curl $URL/props` if a probe passes trivially. """ from __future__ import annotations import argparse import json import random import re import sys import time import urllib.error import urllib.request from pathlib import Path DEFAULT_URL = "http://127.0.0.1:8082" # A sentence repeated/dropped to size the haystack. Generic on purpose: the test # is about finding an arbitrary phrase, not about any domain vocabulary. FILLER_SENTENCES = ( "At 04:{minute} the north yard crew logged pallet {pallet} moving between " "bays {bay_a} and {bay_b} while the dock light stayed green.", "Inventory sheet {sheet} recorded {count} empty crates and {count2} sealed " "drums, with no variance against the morning printout.", "Radio traffic at 11:{minute} covered a delayed inbound truck, a lunch " "rotation, and a tire pressure check on forklift {pallet}.", "The overcast sky and light easterly wind were noted in log entry {sheet} " "as expected for the season, with no impact on operations.", ) NEEDLE_TEMPLATE = ( "IMPORTANT RECORD: the {label} for this document is exactly {nonce}." ) # Nonce parts are chosen so the phrase cannot be inferred, and the question never # repeats it: only retrieval from the document can produce it. NONCE_WORDS = ( "ZEBRA", "ORCHID", "CINDER", "MAPLE", "QUARTZ", "FALCON", "AMBER", "PINE", "COPPER", "VIOLET", "GRANITE", "WILLOW", "SABLE", "TOPAZ", "CEDAR", "LANTERN", "MARLIN", "ONYX", "PEWTER", "RAVEN", "SORREL", "THISTLE", "UMBER", "VERDANT", ) class ProbeError(RuntimeError): pass class Client: """Minimal OpenAI-compatible client with streaming and no HTTP deps.""" def __init__(self, base: str, model: str | None, timeout: float) -> None: self.base = base.rstrip("/") self.model = model self.timeout = timeout self._opener = urllib.request.build_opener(urllib.request.ProxyHandler({})) def _post(self, path: str, body: dict, stream: bool = False, timeout: float | None = None): data = json.dumps(body).encode("utf-8") req = urllib.request.Request( self.base + path, data=data, headers={"Content-Type": "application/json", "Accept": "text/event-stream" if stream else "application/json"}, method="POST", ) try: return self._opener.open(req, timeout=timeout or self.timeout) except urllib.error.HTTPError as exc: detail = exc.read().decode("utf-8", "replace")[:2000] raise ProbeError(f"HTTP {exc.code} from {path}: {detail}") from exc except urllib.error.URLError as exc: raise ProbeError(f"cannot reach {self.base}{path}: {exc.reason}") from exc def get_json(self, path: str) -> dict: try: with self._opener.open(self.base + path, timeout=30) as resp: return json.loads(resp.read().decode("utf-8")) except (urllib.error.URLError, urllib.error.HTTPError, ValueError) as exc: raise ProbeError(f"cannot read {self.base}{path}: {exc}") from exc def resolve_model(self, wanted: str | None) -> str: if wanted: return wanted data = self.get_json("/v1/models") entries = data.get("data") or [] if not entries: raise ProbeError("server reports no loaded model") self.model = entries[0].get("id") or entries[0].get("name") return self.model def chat(self, messages: list[dict], max_tokens: int, on_progress=None, timeout: float | None = None) -> dict: body = { "model": self.model, "messages": messages, "max_tokens": max_tokens, "cache_prompt": True, "stream": True, } started = time.monotonic() chunks: list[str] = [] reasoning: list[str] = [] usage: dict = {} timings: dict = {} finish_reason = None started_report = started with self._post("/v1/chat/completions", body, stream=True, timeout=timeout) as resp: for raw in resp: line = raw.decode("utf-8", "replace").strip() if not line or not line.startswith("data:"): continue payload = line[5:].strip() if payload == "[DONE]": break try: event = json.loads(payload) except ValueError: continue if event.get("usage"): usage = event["usage"] if event.get("timings"): # Later chunks carry cumulative totals; keep the latest. timings = event["timings"] for choice in event.get("choices") or []: if choice.get("finish_reason"): finish_reason = choice["finish_reason"] delta = choice.get("delta") or {} if delta.get("content"): chunks.append(delta["content"]) if delta.get("reasoning_content"): reasoning.append(delta["reasoning_content"]) if on_progress and time.monotonic() - started_report >= 15.0: started_report = time.monotonic() on_progress(len(chunks), time.monotonic() - started) elapsed = time.monotonic() - started return { "content": "".join(chunks), "reasoning": "".join(reasoning), "usage": usage, "timings": timings, "finish_reason": finish_reason, "elapsed_s": elapsed, } def busy_slots(self) -> list[dict] | None: """Slots with a request in flight, or None if /slots is unavailable. The server serves one slot, so a probe sent while another client is generating just queues behind it; that would measure the wrong thing. """ try: data = self.get_json("/slots") except ProbeError: return None if not isinstance(data, list): return None return [s for s in data if isinstance(s, dict) and s.get("is_processing")] def wait_idle(self, poll_s: float = 5.0, timeout_s: float = 3600.0) -> bool: deadline = time.monotonic() + timeout_s announced = False while time.monotonic() < deadline: busy = self.busy_slots() if not busy: return True if not announced: print("preflight: server is busy; waiting for the slot to free up " "(Ctrl-C to abort)", flush=True) announced = True time.sleep(poll_s) return False def build_prompt(target_tokens: int, needle_at: float, nonce: str, label: str, chars_per_token: float, rng: random.Random) -> str: """A ~`target_tokens` document with the needle sentence at `needle_at`. `needle_at` is the fraction of the document's characters that precede the needle (0 = first thing, 1 = last), which is close enough to a token depth at the sizes tested and needs no client-side tokenizer. """ head = "=== FIELD RECORDS ===\n" needle_line = NEEDLE_TEMPLATE.format(label=label, nonce=nonce) + "\n" tail = "\n=== END OF RECORDS ===\n" total_chars = target_tokens * chars_per_token depth = min(max(needle_at, 0.0), 1.0) mid_chars = int(depth * total_chars) before = max(mid_chars - len(needle_line), 0) after = max(int(total_chars) - mid_chars, 0) return ( head + filler_text(before, rng) + "\n" + needle_line + filler_text(after, rng) + tail ) def filler_text(chars: int, rng: random.Random) -> str: parts: list[str] = [] size = 0 i = 0 while size < chars: i += 1 tmpl = rng.choice(FILLER_SENTENCES) line = tmpl.format( minute=f"{rng.randrange(0, 60):02d}", pallet=f"P-{rng.randrange(1000, 9999)}", bay_a=f"B{rng.randrange(1, 40)}", bay_b=f"B{rng.randrange(1, 40)}", sheet=rng.randrange(100000, 999999), count=rng.randrange(10, 999), count2=rng.randrange(10, 999), ) parts.append(f"Entry {i}. {line}") size += len(parts[-1]) + 1 return "\n".join(parts) def make_prompt(target_tokens: int, needle_at: float, nonce: str, label: str, chars_per_token: float, rng: random.Random) -> str: return build_prompt(target_tokens, needle_at, nonce, label, chars_per_token, rng) QUESTION = ("What is the {label} for this document? Reply with the code only.") SYSTEM = ("You answer questions about a long document. Reply with only the " "requested code, with no explanation and no extra words.") ANSWER_SUFFIX = "\n\nQuestion: {question}\nAnswer:" def run_probe(client: Client, *, want_tokens: int, needle_at: float, max_tokens: int, chars_per_token: float, rng: random.Random, retries: int, tolerance: float, verbose: bool, on_progress=None) -> dict: """Size the prompt to `want_tokens` (within tolerance) and grade the answer.""" label = "access phrase" attempt = 0 ratio = chars_per_token while True: attempt += 1 nonce = f"{rng.choice(NONCE_WORDS)}-{rng.randrange(10, 100)}" question = QUESTION.format(label=label) document = make_prompt(want_tokens, needle_at, nonce, label, ratio, rng) messages = [ {"role": "system", "content": SYSTEM}, {"role": "user", "content": document + ANSWER_SUFFIX.format(question=question)}, ] result = client.chat(messages, max_tokens, on_progress=on_progress) usage = result.get("usage") or {} prompt_n = int(usage.get("prompt_tokens") or 0) hit = nonce.lower() in (result["content"] or "").lower() off = abs(prompt_n - want_tokens) / max(want_tokens, 1) # Re-aim when the estimate missed the requested size; a miss at the wrong # size would not be a fair test either way. if off > tolerance and attempt <= retries and prompt_n > 0: # The document overhead is negligible at these sizes, so the observed # error is almost entirely filler scaling. new_ratio = ratio * (want_tokens / prompt_n) if verbose: print(f" resize: asked ~{want_tokens} got {prompt_n} " f"(chars/token {ratio:.2f} -> {new_ratio:.2f})", flush=True) ratio = new_ratio continue return { "want_tokens": want_tokens, "prompt_tokens": prompt_n, "needle_at": needle_at, "nonce": nonce, "hit": hit, "answer": (result["content"] or "").strip(), "reasoning_chars": len(result.get("reasoning") or ""), "finish_reason": result.get("finish_reason"), "elapsed_s": result["elapsed_s"], "usage": usage, "timings": result.get("timings") or {}, "sized": off <= tolerance, "attempts": attempt, } def calibrate(client: Client, rng: random.Random, probe_tokens: int = 1500) -> float: """Estimate characters per token from one short, cheap request.""" filler = filler_text(int(probe_tokens * 3.6), rng) payload = "ping " + filler messages = [ {"role": "system", "content": "Reply with only: OK"}, {"role": "user", "content": payload}, ] result = client.chat(messages, 2, timeout=min(120.0, client.timeout)) prompt_n = int((result.get("usage") or {}).get("prompt_tokens") or 0) if prompt_n <= 0: raise ProbeError("server did not report prompt_tokens during calibration") # Subtract the chat-template/system overhead, roughly 20 tokens here. ratio = len(payload) / max(prompt_n - 20, 1) print(f"calibration: {prompt_n} tokens for {len(payload)} chars " f"(~{ratio:.3f} chars/token)", flush=True) return ratio def human(n: int) -> str: return f"{n / 1024:.1f}k" def main() -> int: ap = argparse.ArgumentParser( description="Probe a running llama-kvmem server with long prompts.") ap.add_argument("max_tokens", type=int, help="maximum prompt size in tokens (the only required argument)") ap.add_argument("--url", default=DEFAULT_URL) ap.add_argument("--model", default=None, help="model id; default: first entry from /v1/models") ap.add_argument("--max-new", type=int, default=64, help="generation cap per probe (default 64)") ap.add_argument("--sizes", default="", help="comma-separated probe sizes; default 1/4,1/2,3/4,1 of MAX") ap.add_argument("--extra-positions", default="0.05,0.5,0.95", help="needle depths probed at MAX (default 0.05,0.5,0.95)") ap.add_argument("--tolerance", type=float, default=0.10, help="accepted |actual-want|/want for a probe size (default 0.10)") ap.add_argument("--retries", type=int, default=2, help="sizing retries per probe (default 2)") ap.add_argument("--wait-idle", action="store_true", help="wait for the server slot to be free before probing") ap.add_argument("--seed", type=int, default=1234) ap.add_argument("--timeout", type=float, default=None, help="HTTP timeout seconds; default 900 or max_tokens/25, whichever larger") ap.add_argument("--json-out", type=Path, default=None, help="write full results as JSON here") ap.add_argument("-q", "--quiet", action="store_true") args = ap.parse_args() if args.max_tokens < 256: ap.error("max_tokens must be at least 256") timeout = args.timeout or max(900.0, args.max_tokens / 25.0) client = Client(args.url, args.model, timeout) try: model = client.resolve_model(args.model) except ProbeError as exc: print(f"FAIL: {exc}", file=sys.stderr) return 2 if args.sizes: sizes = sorted({int(x) for x in args.sizes.split(",") if x.strip()}) else: sizes = sorted({max(1, args.max_tokens * num // den) for num, den in ((1, 4), (1, 2), (3, 4), (1, 1)) if num * args.max_tokens // den >= 256}) if not sizes: sizes = [args.max_tokens] sizes = [s for s in sizes if s <= args.max_tokens] if not sizes: print("FAIL: no probe size at or below max_tokens", file=sys.stderr) return 2 positions = [float(x) for x in args.extra_positions.split(",") if x.strip()] or [0.5] print(f"target : {args.url} model={model}") print(f"max ctx : {args.max_tokens} tokens; probes at " f"{', '.join(human(s) for s in sizes)}") print(f"positions: scaling probes at depth 0.5; MAX also at " f"{', '.join(f'{p:g}' for p in positions)}") print(f"timeout : {timeout:.0f}s per request\n", flush=True) busy = client.busy_slots() if busy: detail = busy[0].get("n_prompt_tokens") or busy[0].get("n_prompt_tokens_processed") print(f"preflight: {len(busy)} slot(s) already processing " f"(n_prompt_tokens={detail}); probes would queue behind that request") if not args.wait_idle: print("preflight: continuing anyway — pass --wait-idle to block first\n", flush=True) elif not client.wait_idle(): print("FAIL: server still busy; not starting probes", file=sys.stderr) return 2 else: print("preflight: slot free, starting\n", flush=True) elif busy is None: print("preflight: /slots unavailable; cannot tell whether the server is busy\n", flush=True) else: print("preflight: server idle\n", flush=True) rng = random.Random(args.seed) try: ratio = calibrate(client, rng) except ProbeError as exc: print(f"FAIL: {exc}", file=sys.stderr) return 2 probes: list[tuple[int, float]] = [(s, 0.5) for s in sizes] for depth in positions: if depth != 0.5: probes.append((args.max_tokens, depth)) rows: list[dict] = [] for index, (want, depth) in enumerate(probes, 1): tag = f"probe {index}/{len(probes)} want={human(want)} depth={depth:g}" print(f"--- {tag}", flush=True) def progress(n_chunks: int, elapsed: float, _want=want) -> None: if not args.quiet: print(f" ... {elapsed:.0f}s prefill/generation, " f"{n_chunks} chunks", flush=True) started = time.monotonic() try: row = run_probe( client, want_tokens=want, needle_at=depth, max_tokens=args.max_new, chars_per_token=ratio, rng=rng, retries=args.retries, tolerance=args.tolerance, verbose=not args.quiet, on_progress=progress, ) except ProbeError as exc: row = {"want_tokens": want, "needle_at": depth, "hit": False, "prompt_tokens": 0, "error": str(exc)} wall = time.monotonic() - started row["wall_s"] = wall row["index"] = index rows.append(row) if row.get("error"): print(f" FAIL: {row['error']} ({wall:.0f}s)", flush=True) continue ratio = max(0.5, ratio * (want / row["prompt_tokens"])) if row["prompt_tokens"] else ratio print( f" n_prompt={row['prompt_tokens']} (want {want}, " f"{'sized' if row['sized'] else 'OFF-TARGET'}) " f"hit={row['hit']} finish={row['finish_reason']} " f"{wall:.0f}s", flush=True, ) print(f" answer: {row['answer'][:160]!r}", flush=True) print("\n================ LONG CONTEXT PROBE ================") print(f"{'want':>9} {'n_prompt':>9} {'depth':>6} {'hit':>4} {'sized':>6} " f"{'wall/s':>8} answer") ok = True for row in rows: sized = "yes" if row.get("sized") else ("-" if row.get("error") else "no") answer = row.get("answer") or row.get("error", "") print(f"{row['want_tokens']:>9} {row.get('prompt_tokens', 0):>9} " f"{row['needle_at']:>6g} {'Y' if row.get('hit') else 'n':>4} " f"{sized:>6} {row['wall_s']:>8.0f} {answer[:60]!r}") if not row.get("hit"): ok = False if args.json_out: args.json_out.parent.mkdir(parents=True, exist_ok=True) args.json_out.write_text(json.dumps( {"url": args.url, "model": model, "max_tokens": args.max_tokens, "chars_per_token": ratio, "probes": rows}, indent=2) + "\n", encoding="utf-8") print(f"\nwrote {args.json_out}") print("\n### Long-context probe: context size, time and throughput\n") print("| ctx (tokens) | depth | wall (s) | prefill (tok/s) | decode (tok/s) | " "gen tokens | finish | answer | hit |") print("|---:|---:|---:|---:|---:|---:|---|---|:--:|") for row in rows: t = row.get("timings") or {} usage = row.get("usage") or {} ctx = row.get("prompt_tokens") or row["want_tokens"] prefill = t.get("prompt_per_second") decode = t.get("predicted_per_second") gen = t.get("predicted_n") or usage.get("completion_tokens") or 0 answer = (row.get("answer") or row.get("error") or "").replace("|", "\\|") prefill_s = f"{prefill:.1f}" if isinstance(prefill, (int, float)) else "n/a" decode_s = f"{decode:.1f}" if isinstance(decode, (int, float)) else "n/a" print(f"| {ctx} | {row['needle_at']:g} | {row['wall_s']:.0f} | {prefill_s} " f"| {decode_s} | {gen} | {row.get('finish_reason') or '-'} " f"| {answer[:40]!r} | {'yes' if row.get('hit') else 'NO'} |") print("\nwall = full request round trip; prefill/decode are the server's own " "`timings` (tok/s); ctx is the measured `usage.prompt_tokens`.") if ok: print(f"\nPASS: retrieved the buried phrase in all {len(rows)} prompts " f"up to {human(args.max_tokens)} tokens") return 0 failed = [f"{human(r['want_tokens'])}@{r['needle_at']:g}" for r in rows if not r.get("hit")] print(f"\nFAIL: no answer at {', '.join(failed)}", file=sys.stderr) return 1 if __name__ == "__main__": raise SystemExit(main()) -
KVmen技术作者视频:https://www.bilibili.com/video/BV19ybv6cE37/?spm_id_from=333.788.top_right_bar_window_history.content.click&vd_source=75586dc86971419da23353de859d40eb
部署整合包作者视频:https://www.bilibili.com/video/BV1Kzhq6cEy4/?spm_id_from=333.1387.homepage.video_card.click&vd_source=75586dc86971419da23353de859d40eb -
Qwen3.8:27b,24GB显存没准128K上下文能放得下,至少我的7900XTX就能放得下,甚至能开256K上下文
几个关键点:
- 从ggml(llama.cpp官方)下载几个模型
- Qwen3.8-27B-Q4_K_M.gguf(官方的主模型不带MTP)
- mtp-Qwen3.8-27B-Q4_0.gguf(关键,有些模型内置MTP是Q8_0量化的)
- mmproj-Qwen3.8-27B-Q8_0.gguf(多模态视觉塔,需要视觉就加上它)
- KV量化要调成q4_0,MTP量化也要调成q4_0
-m /models/Qwen3.8-27B-Q4_K_M.gguf \ --mmproj /models/mmproj-Qwen3.8-27B-Q8_0.gguf --image-min-tokens 1024 \ --n-gpu-layers 999 \ --ctx-size 131072 \ --cache-type-k q4_0 --cache-type-v q4_0 \ --flash-attn on \ --spec-draft-model /models/mtp-Qwen3.8-27B-Q4_0.gguf \ --spec-type draft-mtp --spec-draft-n-max 3 --spec-draft-p-min 0.1 \ --spec-draft-type-k q4_0 --spec-draft-type-v q4_0 \-
上下文深度探测是有意义的,我手里的两张卡,在上下文超过128K之后,decode都会跌到不到20 tok/s,所以实测之后发现128K上下文基本上就是这个模型的甜点位置
-
16GB和以下的显卡,主模型都放不下
-
-
@snailium
KV量化放到4bit, 实际工作怎么样? 我一直没太敢把KV调低, 一直用的8bit量化, 怕它丢东西.128k 基本上能完成大部分任务了, 但是我一般还是放到256k, 不是要真的用满256k, 而是减少其压缩的次数, 能节省些时间.
-
-
-
-
-
补充一下,@tony-wang 是对的,dsh默认预留64k上下文窗口,也就是说后端开128k上下文,大概填到60k的时候就会触发上下文压缩(compaction)。所以一次性开到256k的做法是对的。
我看看能不能把上下文调优做到插件里面
-
-
-
-
@fcme 另外,大神,我比较好奇,你怎么能在调了预留量之后,让已经进行的会话立即生效?
多轮代码检查之后发现,这些数值都是在会话开始的时候就投影(projection)在会话头信息里面的,然后就没法改了。这是dsh的安全规范操作。
目前我能找到最简单的方法,就是重写当前preset(比如标准模式),然后通过fork会话让新值生效
-
-
-