Your browser does not seem to support JavaScript. As a result, your viewing experience will be diminished, and you have been placed in read-only mode.
Please download a browser that supports JavaScript, or enable it if it's disabled (i.e. NoScript).
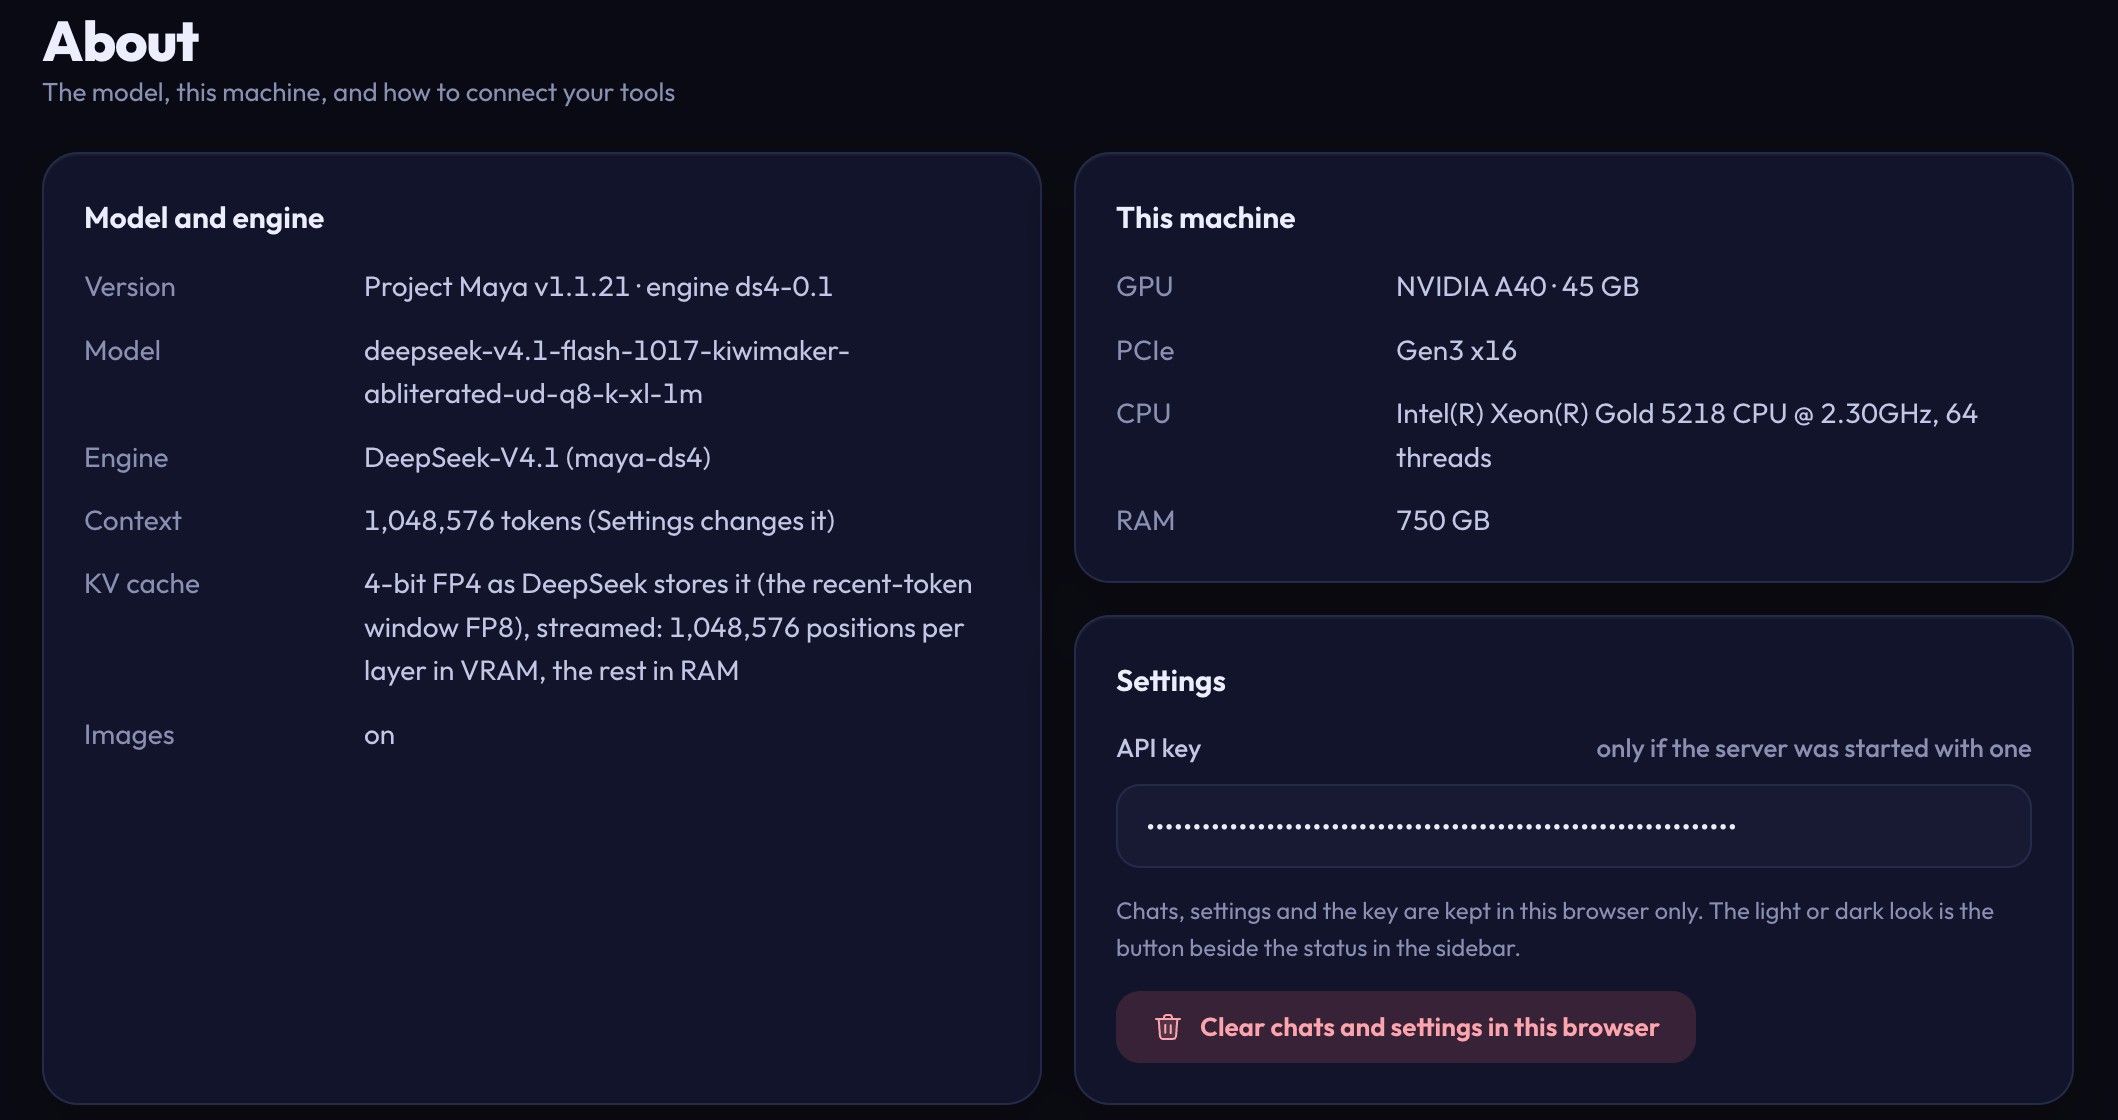
我在我的A40,48G显存+768G内存上,把DeepSeek-V4.1-Flash-1017的Q8量化,模型全放内存读,平均跑到了26T/S。已经有实用价值了,给项目提了PR,看能不能合并进去!专给大内存用户使用! https://github.com/mw00/project-maya/pull/368

 T