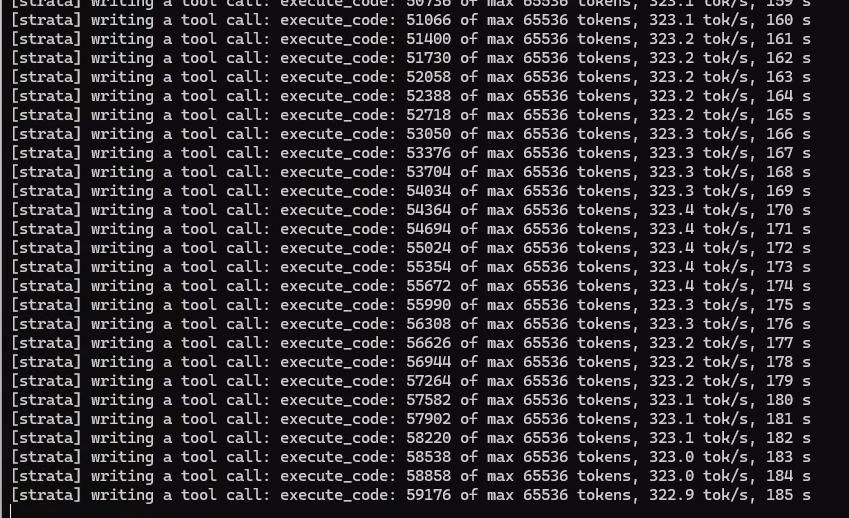
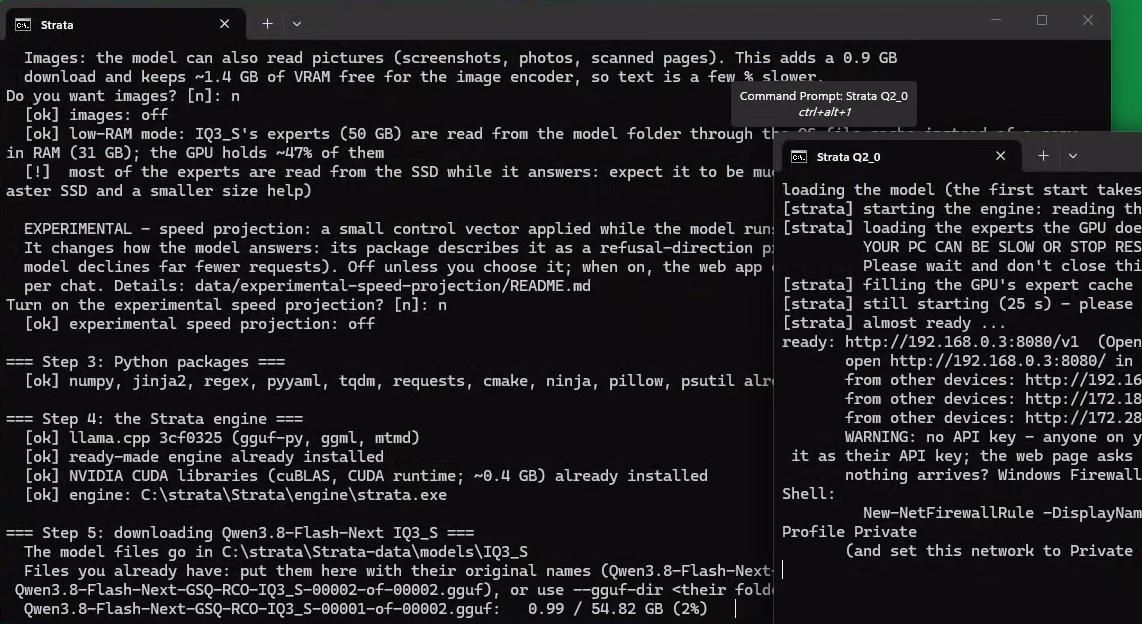
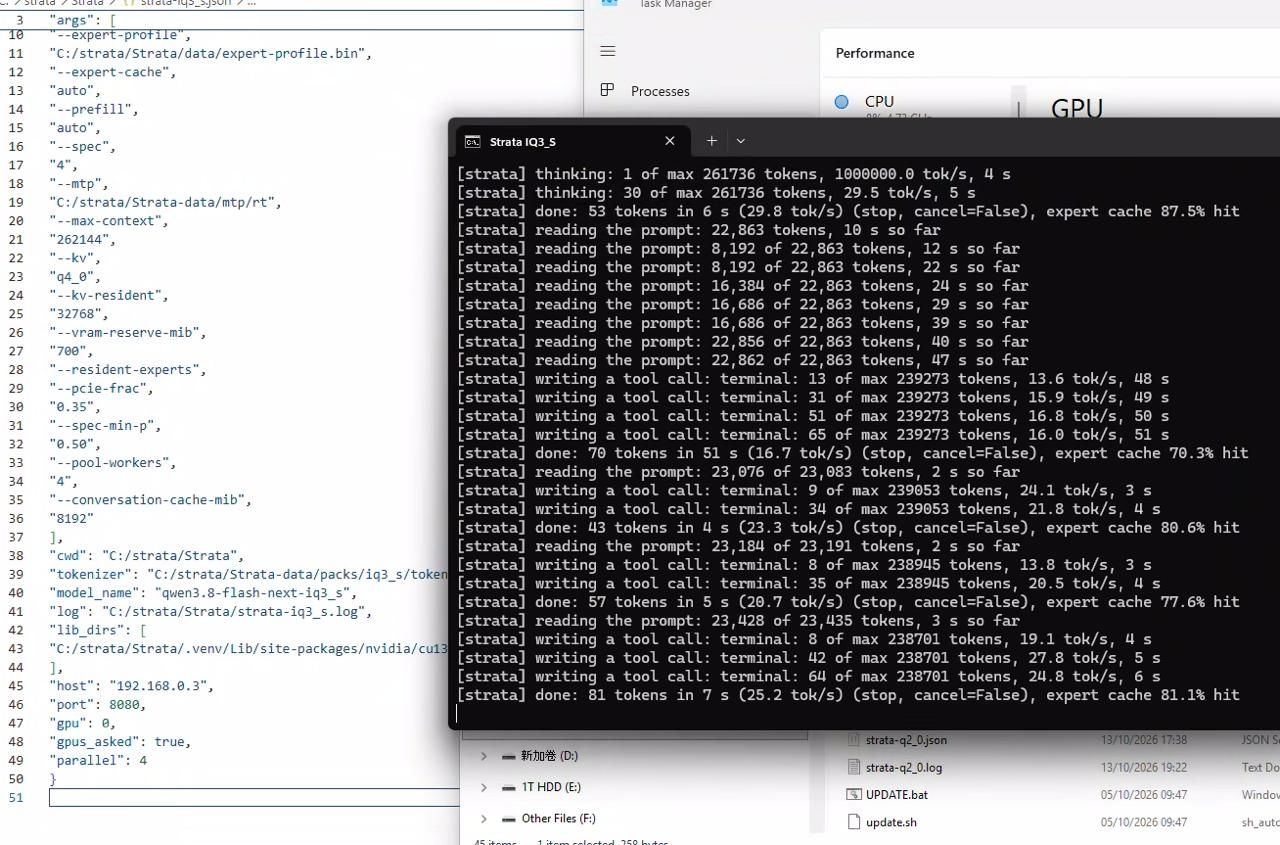
请教各位大神,5090 上 stara 如何支持多线程能快点啊?
-
另外,还可以把他们拉到一起 放到 telegrame 里开会 * T_T*。
重大发现 @perter 你真的是太牛逼了
loading the model (the first start takes a minute or two) ...
[strata] starting the engine: reading the model's weights ...
[strata] loading the experts the GPU does not hold into RAM (of about 38 GB) and locking part of them for the GPU.
YOUR PC CAN BE SLOW OR STOP RESPONDING FOR 1-3 MINUTES NOW - this is normal.
Please wait and don't close this window; the browser opens when it is ready.
[strata] filling the GPU's expert cache (11869 experts, 15.28 GiB of VRAM) ...
[strata] almost ready ...
ready: http://192.168.0.3:8080/v1 (OpenAI: /v1/chat/completions, Anthropic: /v1/messages, context 131072 tokens)
open http://192.168.0.3:8080/ in a browser to chat; close this window to stop the model
from other devices: http://192.168.0.3:8080/ (API: http://192.168.0.3:8080/v1)
from other devices: http://172.18.224.1:8080/ (API: http://172.18.224.1:8080/v1)
from other devices: http://172.28.224.1:8080/ (API: http://172.28.224.1:8080/v1)
WARNING: no API key - anyone on your network can use this model. Add "api_key": "..." to the config (clients send it as their API key; the web page asks for it)
nothing arrives? Windows Firewall blocks it until allowed: accept its prompt for Python, or run in an admin PowerShell:
New-NetFirewallRule -DisplayName "Strata 8080" -Direction Inbound -Protocol TCP -LocalPort 8080 -Action Allow -Profile Private
(and set this network to Private in Windows' network settings)
[strata] reading the prompt: 8,192 of 63,400 tokens, 3 s so far
[strata] reading the prompt: 13,362 of 63,400 tokens, 6 s so far
[strata] reading the prompt: 21,554 of 63,400 tokens, 10 s so far
[strata] reading the prompt: 143 of 148 tokens, 6 s so far
[strata] reading the prompt: 29,746 of 63,400 tokens, 15 s so far
[strata] thinking: 3 of max 130916 tokens, 0.9 tok/s, 10 s
[strata] done: 43 tokens in 10 s (10.9 tok/s) (stop, cancel=False), expert cache 76.0% hit
[strata] reading the prompt: 37,938 of 63,400 tokens, 18 s so far
[strata] reading the prompt: 46,130 of 63,400 tokens, 21 s so far
[strata] reading the prompt: 54,322 of 63,400 tokens, 24 s so far
[strata] reading the prompt: 62,514 of 63,400 tokens, 27 s so far
[strata] reading the prompt: 63,395 of 63,400 tokens, 30 s so far
[strata] thinking: 2 of max 65536 tokens, 3.5 tok/s, 31 s
[strata] reading the prompt: 162 of 167 tokens, 4 s so far
[strata] thinking: 3 of max 65536 tokens, 1.9 tok/s, 32 s
[strata] done: 40 tokens in 5 s (58.2 tok/s) (stop, cancel=False), expert cache 75.8% hit
[strata] thinking: 45 of max 65536 tokens, 16.4 tok/s, 33 s
[strata] answering: 137 of max 65536 tokens, 36.3 tok/s, 34 s
[strata] done: 172 tokens in 35 s (41.8 tok/s) (stop, cancel=False), expert cache 77.2% hit
[strata] response_format json_schema: the Python package jsonschema is not installed, so answers are only checked to be one JSON object (python -m pip install "jsonschema>=4.23,<5")
[strata] reading the prompt: 332 of 339 tokens, 2 s so far
[strata] reading the prompt: 8,192 of 16,007 tokens, 5 s so far
[strata] answering: 4 of max 130725 tokens, 1.3 tok/s, 5 s
[strata] done: 8 tokens in 5 s (2.5 tok/s) (stop, cancel=False), expert cache 63.7% hit
[strata] reading the prompt: 15,994 of 16,007 tokens, 8 s so far
[strata] answering: 5 of max 65536 tokens, 12.7 tok/s, 9 s
[strata] answering: 117 of max 65536 tokens, 83.7 tok/s, 10 s
[strata] done: 156 tokens in 11 s (88.4 tok/s) (stop, cancel=False), expert cache 90.1% hit
[strata] answering: 72 of max 130878 tokens, 99.0 tok/s, 1 s
[strata] done: 84 tokens in 1 s (100.4 tok/s) (stop, cancel=False), expert cache 94.4% hit
[strata] reading the prompt: 63,532 of 63,537 tokens, 1 s so far
[strata] done: 110 tokens in 2 s (129.2 tok/s) (stop, cancel=False), expert cache 96.7% hit
[strata] reading the prompt: 16,169 of 16,176 tokens, 1 s so far
[strata] done: 75 tokens in 2 s (128.9 tok/s) (stop, cancel=False), expert cache 94.1% hit
[strata] thinking: 53 of max 130826 tokens, 109.6 tok/s, 1 s
[strata] done: 76 tokens in 1 s (116.6 tok/s) (stop, cancel=False), expert cache 95.4% hit
[strata] writing a tool call: terminal: 62 of max 65536 tokens, 99.9 tok/s, 1 s
[strata] writing a tool call: terminal: 171 of max 65536 tokens, 104.2 tok/s, 2 s
[strata] done: 214 tokens in 2 s (107.6 tok/s) (stop, cancel=False), expert cache 81.0% hit
[strata] reading the prompt: 685 of 692 tokens, 1 s so far
[strata] done: 4 tokens in 2 s (235.1 tok/s) (stop, cancel=False), expert cache 89.9% hit
[strata] reading the prompt: 18,004 of 18,011 tokens, 3 s so far
[strata] writing a tool call: search_files: 104 of max 65536 tokens, 131.0 tok/s, 4 s
[strata] done: 165 tokens in 4 s (133.9 tok/s) (stop, cancel=False), expert cache 94.0% hit
[strata] reading the prompt: 18,581 of 18,588 tokens, 1 s so far
[strata] done: 101 tokens in 2 s (144.6 tok/s) (stop, cancel=False), expert cache 92.3% hit
[strata] writing a tool call: terminal: 134 of max 65536 tokens, 154.8 tok/s, 1 s
[strata] done: 152 tokens in 1 s (153.7 tok/s) (stop, cancel=False), expert cache 94.2% hit
[strata] reading the prompt: 19,179 of 19,186 tokens, 1 s so far
[strata] done: 140 tokens in 2 s (170.5 tok/s) (stop, cancel=False), expert cache 94.4% hit
[strata] reading the prompt: 19,731 of 19,738 tokens, 1 s so far
[strata] done: 30 tokens in 2 s (181.3 tok/s) (stop, cancel=False), expert cache 94.2% hit
[strata] reading the prompt: 20,373 of 20,380 tokens, 2 s so far
[strata] done: 114 tokens in 2 s (147.1 tok/s) (stop, cancel=False), expert cache 92.2% hit
[strata] writing a tool call: execute_code: 36 of max 65536 tokens, 162.0 tok/s, 1 s
[strata] done: 158 tokens in 2 s (173.4 tok/s) (stop, cancel=False), expert cache 95.7% hit
[strata] writing a tool call: execute_code: 40 of max 65536 tokens, 197.4 tok/s, 1 s
[strata] done: 146 tokens in 2 s (170.8 tok/s) (stop, cancel=False), expert cache 95.6% hit
[strata] reading the prompt: 21,781 of 21,788 tokens, 2 s so far
[strata] writing a tool call: execute_code: 130 of max 65536 tokens, 151.6 tok/s, 3 s
[strata] done: 183 tokens in 3 s (152.0 tok/s) (stop, cancel=False), expert cache 95.8% hit
[strata] reading the prompt: 23,252 of 23,259 tokens, 3 s so far
[strata] reading the prompt: 257 of 262 tokens, 3 s so far
[strata] reading the prompt: 4 of max 65536 tokens, 3.5 tok/s, 4 s
[strata] done: 27 tokens in 4 s (54.7 tok/s) (stop, cancel=False), expert cache 93.3% hit
[strata] writing a tool call: execute_code: 92 of max 65536 tokens, 42.7 tok/s, 5 s
[strata] done: 198 tokens in 6 s (71.2 tok/s) (stop, cancel=False), expert cache 96.7% hit
[strata] writing a tool call: execute_code: 18 of max 65536 tokens, 209.1 tok/s, 1 s
[strata] done: 147 tokens in 2 s (188.9 tok/s) (stop, cancel=False), expert cache 96.0% hit
[strata] reading the prompt: 393 of 400 tokens, 1 s so far
[strata] done: 4 tokens in 1 s (173.7 tok/s) (stop, cancel=False), expert cache 84.4% hit
[strata] reading the prompt: 24,031 of 24,038 tokens, 2 s so far
[strata] writing a tool call: execute_code: 149 of max 65536 tokens, 170.6 tok/s, 3 s
[strata] done: 178 tokens in 3 s (176.1 tok/s) (stop, cancel=False), expert cache 96.3% hit
[strata] writing a tool call: execute_code: 10 of max 65536 tokens, 167.9 tok/s, 1 s
[strata] writing a tool call: execute_code: 203 of max 65536 tokens, 188.2 tok/s, 2 s
[strata] done: 319 tokens in 3 s (186.0 tok/s) (stop, cancel=False), expert cache 96.2% hit
[strata] reading the prompt: 25,276 of 25,283 tokens, 2 s so far
[strata] writing a tool call: execute_code: 150 of max 65536 tokens, 171.4 tok/s, 3 s
[strata] done: 281 tokens in 3 s (181.6 tok/s) (stop, cancel=False), expert cache 95.0% hit
[strata] reading the prompt: 26,374 of 26,381 tokens, 1 s so far
[strata] answering: 70 of max 65536 tokens, 82.1 tok/s, 3 s
[strata] answering: 185 of max 65536 tokens, 99.6 tok/s, 4 s
[strata] answering: 286 of max 65536 tokens, 99.6 tok/s, 5 s
[strata] done: 331 tokens in 5 s (102.1 tok/s) (stop, cancel=False), expert cache 88.3% hit
[strata] reading the prompt: 28,957 of 28,964 tokens, 3 s so far
[strata] done: 43 tokens in 3 s (88.8 tok/s) (stop, cancel=False), expert cache 80.0% hit
[strata] reading the prompt: 32,102 of 32,109 tokens, 3 s so far
[strata] done: 67 tokens in 4 s (108.6 tok/s) (stop, cancel=False), expert cache 84.8% hit
[strata] reading the prompt: 32,783 of 32,790 tokens, 2 s so far
[strata] writing a tool call: read_file: 108 of max 65536 tokens, 120.1 tok/s, 3 s
[strata] done: 111 tokens in 3 s (123.4 tok/s) (stop, cancel=False), expert cache 84.6% hit
[strata] reading the prompt: 33,542 of 33,549 tokens, 2 s so far
[strata] writing a tool call: execute_code: 116 of max 65536 tokens, 126.6 tok/s, 3 s
[strata] done: 173 tokens in 4 s (128.8 tok/s) (stop, cancel=False), expert cache 89.3% hit
[strata] reading the prompt: 34,115 of 34,122 tokens, 1 s so far
[strata] writing a tool call: execute_code: 120 of max 65536 tokens, 136.6 tok/s, 2 s
[strata] done: 176 tokens in 3 s (142.8 tok/s) (stop, cancel=False), expert cache 93.2% hit
[strata] reading the prompt: 34,861 of 34,868 tokens, 2 s so far
[strata] writing a tool call: execute_code: 115 of max 65536 tokens, 131.4 tok/s, 3 s
[strata] done: 192 tokens in 3 s (135.5 tok/s) (stop, cancel=False), expert cache 93.2% hit
[strata] reading the prompt: 35,986 of 35,993 tokens, 2 s so far
[strata] answering: 81 of max 65536 tokens, 94.2 tok/s, 3 s
[strata] done: 175 tokens in 4 s (115.1 tok/s) (stop, cancel=False), expert cache 91.1% hit
[strata] reading the prompt: 37,260 of 37,267 tokens, 3 s so far
[strata] answering: 118 of max 65536 tokens, 143.9 tok/s, 4 s
[strata] writing a tool call: skill_manage: 260 of max 65536 tokens, 141.7 tok/s, 5 s
[strata] writing a tool call: skill_manage: 380 of max 65536 tokens, 132.0 tok/s, 6 s
[strata] writing a tool call: skill_manage: 486 of max 65536 tokens, 124.9 tok/s, 7 s
[strata] writing a tool call: skill_manage: 628 of max 65536 tokens, 128.1 tok/s, 8 s
[strata] done: 635 tokens in 8 s (128.3 tok/s) (stop, cancel=False), expert cache 89.8% hit
[strata] writing a tool call: skill_manage: 123 of max 65536 tokens, 157.8 tok/s, 1 s
[strata] writing a tool call: skill_manage: 311 of max 65536 tokens, 173.4 tok/s, 2 s
[strata] writing a tool call: skill_manage: 469 of max 65536 tokens, 167.8 tok/s, 3 s
[strata] done: 498 tokens in 3 s (168.8 tok/s) (stop, cancel=False), expert cache 87.2% hit
[strata] reading the prompt: 38,509 of 38,516 tokens, 2 s so far
[strata] answering: 68 of max 65536 tokens, 78.5 tok/s, 3 s
[strata] writing a tool call: skill_manage: 200 of max 65536 tokens, 106.5 tok/s, 4 s
[strata] writing a tool call: skill_manage: 305 of max 65536 tokens, 105.5 tok/s, 5 s
[strata] done: 358 tokens in 5 s (112.3 tok/s) (stop, cancel=False), expert cache 86.8% hit
[strata] answering: 71 of max 65536 tokens, 101.8 tok/s, 1 s
[strata] answering: 192 of max 65536 tokens, 112.3 tok/s, 2 s
[strata] done: 199 tokens in 2 s (110.9 tok/s) (stop, cancel=False), expert cache 93.1% hit
[strata] reading the prompt: 29,114 of 29,121 tokens, 3 s so far
[strata] writing a tool call: terminal: 53 of max 65536 tokens, 84.2 tok/s, 4 s
[strata] writing a tool call: execute_code: 177 of max 65536 tokens, 108.4 tok/s, 5 s
[strata] writing a tool call: execute_code: 326 of max 65536 tokens, 122.9 tok/s, 6 s
[strata] writing a tool call: execute_code: 454 of max 65536 tokens, 122.8 tok/s, 7 s
[strata] done: 535 tokens in 8 s (126.8 tok/s) (stop, cancel=False), expert cache 86.1% hit
[strata] reading the prompt: 30,449 of 30,456 tokens, 2 s so far
[strata] writing a tool call: execute_code: 134 of max 65536 tokens, 163.2 tok/s, 3 s
[strata] writing a tool call: execute_code: 320 of max 65536 tokens, 174.9 tok/s, 4 s
[strata] done: 376 tokens in 4 s (171.9 tok/s) (stop, cancel=False), expert cache 94.8% hit
[strata] reading the prompt: 32,621 of 32,628 tokens, 3 s so far
[strata] writing a tool call: execute_code: 100 of max 65536 tokens, 127.9 tok/s, 4 s
[strata] writing a tool call: execute_code: 273 of max 65536 tokens, 152.8 tok/s, 5 s
[strata] writing a tool call: execute_code: 431 of max 65536 tokens, 154.5 tok/s, 6 s
[strata] done: 459 tokens in 6 s (157.4 tok/s) (stop, cancel=False), expert cache 94.7% hit
[strata] reading the prompt: 34,604 of 34,611 tokens, 3 s so far
[strata] writing a tool call: execute_code: 137 of max 65536 tokens, 172.6 tok/s, 4 s
[strata] writing a tool call: execute_code: 286 of max 65536 tokens, 158.4 tok/s, 5 s
[strata] done: 380 tokens in 5 s (164.6 tok/s) (stop, cancel=False), expert cache 95.0% hit
[strata] reading the prompt: 2 of max 65536 tokens, 37.4 tok/s, 1 s
[strata] writing a tool call: execute_code: 182 of max 65536 tokens, 170.3 tok/s, 2 s
[strata] done: 254 tokens in 2 s (170.7 tok/s) (stop, cancel=False), expert cache 95.0% hit
[strata] reading the prompt: 434 of 441 tokens, 1 s so far
[strata] done: 4 tokens in 1 s (67.7 tok/s) (stop, cancel=False), expert cache 77.5% hit
[strata] reading the prompt: 31,482 of 35,584 tokens, 3 s so far
[strata] reading the prompt: 35,577 of 35,584 tokens, 6 s so far
[strata] writing a tool call: execute_code: 88 of max 65536 tokens, 193.0 tok/s, 7 s
[strata] writing a tool call: execute_code: 250 of max 65536 tokens, 168.9 tok/s, 8 s
[strata] done: 268 tokens in 8 s (168.1 tok/s) (stop, cancel=False), expert cache 94.0% hit
[strata] reading the prompt: 452 of 459 tokens, 2 s so far
[strata] done: 4 tokens in 2 s (181.7 tok/s) (stop, cancel=False), expert cache 83.0% hit
[strata] reading the prompt: 36,015 of 36,016 tokens, 1 s so far
[strata] writing a tool call: execute_code: 189 of max 65536 tokens, 188.2 tok/s, 2 s
[strata] done: 274 tokens in 3 s (185.0 tok/s) (stop, cancel=False), expert cache 93.9% hit
[strata] reading the prompt: 458 of 465 tokens, 1 s so far
[strata] done: 4 tokens in 2 s (71.4 tok/s) (stop, cancel=False), expert cache 84.2% hit
[strata] reading the prompt: 36,454 of 36,455 tokens, 1 s so far
[strata] writing a tool call: execute_code: 192 of max 65536 tokens, 193.2 tok/s, 2 s
[strata] done: 269 tokens in 3 s (184.7 tok/s) (stop, cancel=False), expert cache 93.1% hit
[strata] reading the prompt: 453 of 460 tokens, 1 s so far
[strata] done: 4 tokens in 2 s (70.7 tok/s) (stop, cancel=False), expert cache 83.6% hit
[strata] reading the prompt: 36,881 of 36,888 tokens, 1 s so far
[strata] writing a tool call: execute_code: 168 of max 65536 tokens, 185.1 tok/s, 2 s
[strata] done: 269 tokens in 3 s (181.6 tok/s) (stop, cancel=False), expert cache 92.7% hit
[strata] reading the prompt: 453 of 460 tokens, 2 s so far
[strata] done: 4 tokens in 2 s (69.5 tok/s) (stop, cancel=False), expert cache 82.8% hit
[strata] reading the prompt: 37,299 of 37,300 tokens, 1 s so far
[strata] writing a tool call: execute_code: 184 of max 65536 tokens, 185.8 tok/s, 2 s
[strata] done: 269 tokens in 3 s (174.9 tok/s) (stop, cancel=False), expert cache 92.4% hit
[strata] reading the prompt: 453 of 460 tokens, 2 s so far
[strata] done: 4 tokens in 2 s (163.1 tok/s) (stop, cancel=False), expert cache 82.0% hit
[strata] reading the prompt: 37,727 of 37,734 tokens, 1 s so far
[strata] writing a tool call: execute_code: 165 of max 65536 tokens, 177.9 tok/s, 2 s
[strata] done: 269 tokens in 3 s (173.6 tok/s) (stop, cancel=False), expert cache 91.9% hit
[strata] reading the prompt: 453 of 460 tokens, 2 s so far
[strata] done: 4 tokens in 2 s (181.6 tok/s) (stop, cancel=False), expert cache 81.2% hit
[strata] reading the prompt: 38,158 of 38,165 tokens, 1 s so far
[strata] writing a tool call: execute_code: 166 of max 65536 tokens, 185.7 tok/s, 2 s
[strata] done: 272 tokens in 3 s (177.2 tok/s) (stop, cancel=False), expert cache 92.3% hit
[strata] reading the prompt: 456 of 463 tokens, 2 s so far
[strata] done: 4 tokens in 2 s (181.7 tok/s) (stop, cancel=False), expert cache 81.2% hit
[strata] reading the prompt: 38,573 of 38,580 tokens, 1 s so far
[strata] writing a tool call: execute_code: 161 of max 65536 tokens, 181.1 tok/s, 2 s
[strata] done: 271 tokens in 3 s (175.3 tok/s) (stop, cancel=False), expert cache 91.5% hit
[strata] reading the prompt: 455 of 462 tokens, 2 s so far
[strata] done: 4 tokens in 2 s (159.8 tok/s) (stop, cancel=False), expert cache 80.6% hit
[strata] reading the prompt: 38,987 of 38,994 tokens, 1 s so far
[strata] writing a tool call: execute_code: 165 of max 65536 tokens, 178.7 tok/s, 2 s
[strata] done: 271 tokens in 3 s (170.4 tok/s) (stop, cancel=False), expert cache 91.3% hit
[strata] reading the prompt: 455 of 462 tokens, 2 s so far
[strata] done: 4 tokens in 2 s (63.4 tok/s) (stop, cancel=False), expert cache 81.1% hit
[strata] reading the prompt: 39,400 of 39,407 tokens, 1 s so far
[strata] writing a tool call: execute_code: 165 of max 65536 tokens, 183.1 tok/s, 2 s
[strata] done: 272 tokens in 3 s (167.5 tok/s) (stop, cancel=False), expert cache 91.0% hit
[strata] reading the prompt: 456 of 463 tokens, 2 s so far
[strata] done: 4 tokens in 2 s (170.0 tok/s) (stop, cancel=False), expert cache 79.7% hit
[strata] reading the prompt: 39,815 of 39,822 tokens, 1 s so far
[strata] writing a tool call: execute_code: 165 of max 65536 tokens, 175.7 tok/s, 2 s
[strata] done: 271 tokens in 3 s (170.7 tok/s) (stop, cancel=False), expert cache 90.9% hit
[strata] reading the prompt: 455 of 462 tokens, 2 s so far
[strata] done: 4 tokens in 2 s (58.3 tok/s) (stop, cancel=False), expert cache 80.2% hit
[strata] reading the prompt: 40,229 of 40,236 tokens, 1 s so far
[strata] writing a tool call: execute_code: 169 of max 65536 tokens, 181.7 tok/s, 2 s
[strata] done: 271 tokens in 3 s (176.4 tok/s) (stop, cancel=False), expert cache 90.8% hit
[strata] reading the prompt: 455 of 462 tokens, 2 s so far
[strata] done: 4 tokens in 2 s (71.4 tok/s) (stop, cancel=False), expert cache 80.0% hit
[strata] reading the prompt: 40,643 of 40,650 tokens, 1 s so far
[strata] writing a tool call: execute_code: 162 of max 65536 tokens, 184.2 tok/s, 2 s
[strata] done: 272 tokens in 3 s (177.6 tok/s) (stop, cancel=False), expert cache 91.0% hit
[strata] reading the prompt: 456 of 463 tokens, 2 s so far
[strata] done: 4 tokens in 2 s (66.1 tok/s) (stop, cancel=False), expert cache 79.4% hit
[strata] reading the prompt: 41,058 of 41,065 tokens, 1 s so far
[strata] writing a tool call: execute_code: 157 of max 65536 tokens, 170.7 tok/s, 2 s
[strata] done: 273 tokens in 3 s (162.0 tok/s) (stop, cancel=False), expert cache 90.8% hit
[strata] reading the prompt: 457 of 464 tokens, 2 s so far
[strata] done: 4 tokens in 2 s (66.1 tok/s) (stop, cancel=False), expert cache 78.3% hit
[strata] reading the prompt: 41,474 of 41,481 tokens, 1 s so far
[strata] writing a tool call: execute_code: 159 of max 65536 tokens, 177.6 tok/s, 2 s
[strata] done: 277 tokens in 3 s (164.0 tok/s) (stop, cancel=False), expert cache 90.2% hit现在多开,来回切agents 爽到极致啊, 我感觉比 27b 都快,而且现在这工作质量真的太棒了! 感谢锤子兄弟提供这么好的地方,感谢peter 感谢论坛里的大神们。
不过现在问题来了,我刚订的 max x5 ultra 96 是不是应该退掉,是不是会被完败,请大神们赐教 Thanks♪(・ω・)ノ
-
"--conversation-cache-mib", "8192"
感谢 Perter 的回复。 我实验了 还是不行
loading the model (the first start takes a minute or two) ...
[strata] starting the engine: reading the model's weights ...
[strata] loading the experts the GPU does not hold into RAM (of about 38 GB) and locking part of them for the GPU.
YOUR PC CAN BE SLOW OR STOP RESPONDING FOR 1-3 MINUTES NOW - this is normal.
Please wait and don't close this window; the browser opens when it is ready.
[strata] filling the GPU's expert cache (17731 experts, 22.83 GiB of VRAM) ...
[strata] still starting (24 s) - please wait ...
[strata] almost ready ...
ready: http://192.168.0.3:8080/v1 (OpenAI: /v1/chat/completions, Anthropic: /v1/messages, context 131072 tokens)
open http://192.168.0.3:8080/ in a browser to chat; close this window to stop the model
from other devices: http://192.168.0.3:8080/ (API: http://192.168.0.3:8080/v1)
from other devices: http://172.18.224.1:8080/ (API: http://172.18.224.1:8080/v1)
from other devices: http://172.28.224.1:8080/ (API: http://172.28.224.1:8080/v1)
WARNING: no API key - anyone on your network can use this model. Add "api_key": "..." to the config (clients send it as their API key; the web page asks for it)
nothing arrives? Windows Firewall blocks it until allowed: accept its prompt for Python, or run in an admin PowerShell:
New-NetFirewallRule -DisplayName "Strata 8080" -Direction Inbound -Protocol TCP -LocalPort 8080 -Action Allow -Profile Private
(and set this network to Private in Windows' network settings)
[strata] thinking: 20 of max 130987 tokens, 109.5 tok/s, 1 s
[strata] done: 42 tokens in 1 s (117.4 tok/s) (stop, cancel=False), expert cache 96.5% hit (+0.4% of the routed experts over PCIe)
[strata] reading the prompt: 8,192 of 20,055 tokens, 2 s so far
[strata] reading the prompt: 16,384 of 20,055 tokens, 4 s so far
[strata] reading the prompt: 20,048 of 20,055 tokens, 6 s so far
[strata] answering: 70 of max 111009 tokens, 124.6 tok/s, 7 s
[strata] answering: 203 of max 111009 tokens, 129.1 tok/s, 8 s
[strata] answering: 375 of max 111009 tokens, 142.9 tok/s, 9 s
[strata] answering: 563 of max 111009 tokens, 154.9 tok/s, 10 s
[strata] answering: 741 of max 111009 tokens, 159.8 tok/s, 11 s
[strata] answering: 942 of max 111009 tokens, 166.9 tok/s, 12 s
[strata] answering: 1112 of max 111009 tokens, 167.1 tok/s, 13 s
[strata] answering: 1328 of max 111009 tokens, 173.4 tok/s, 14 s
[strata] answering: 1572 of max 111009 tokens, 181.3 tok/s, 15 s
[strata] answering: 1810 of max 111009 tokens, 186.8 tok/s, 16 s
[strata] answering: 2058 of max 111009 tokens, 192.3 tok/s, 17 s
[strata] answering: 2303 of max 111009 tokens, 196.7 tok/s, 18 s
[strata] answering: 2566 of max 111009 tokens, 201.9 tok/s, 19 s
[strata] answering: 2792 of max 111009 tokens, 203.2 tok/s, 20 s
[strata] answering: 3054 of max 111009 tokens, 207.1 tok/s, 21 s
[strata] answering: 3337 of max 111009 tokens, 211.8 tok/s, 22 s
[strata] answering: 3606 of max 111009 tokens, 215.1 tok/s, 23 s
[strata] answering: 3864 of max 111009 tokens, 217.5 tok/s, 24 s
[strata] answering: 4061 of max 111009 tokens, 216.4 tok/s, 25 s
[strata] answering: 4328 of max 111009 tokens, 218.8 tok/s, 26 s
[strata] answering: 4586 of max 111009 tokens, 220.4 tok/s, 27 s
[strata] answering: 4862 of max 111009 tokens, 222.9 tok/s, 28 s
[strata] answering: 5165 of max 111009 tokens, 226.3 tok/s, 29 s
[strata] answering: 5447 of max 111009 tokens, 228.5 tok/s, 30 s
[strata] answering: 5659 of max 111009 tokens, 227.7 tok/s, 31 s
[strata] answering: 5856 of max 111009 tokens, 226.4 tok/s, 32 s
[strata] answering: 5997 of max 111009 tokens, 223.0 tok/s, 33 s
[strata] answering: 6145 of max 111009 tokens, 220.3 tok/s, 34 s
[strata] answering: 6332 of max 111009 tokens, 219.1 tok/s, 35 s
[strata] answering: 6545 of max 111009 tokens, 218.8 tok/s, 36 s
[strata] answering: 6797 of max 111009 tokens, 219.8 tok/s, 37 s
[strata] answering: 7017 of max 111009 tokens, 219.8 tok/s, 38 s
[strata] answering: 7258 of max 111009 tokens, 220.3 tok/s, 39 s
[strata] answering: 7548 of max 111009 tokens, 222.2 tok/s, 40 s
[strata] answering: 7801 of max 111009 tokens, 223.0 tok/s, 41 s
[strata] answering: 8072 of max 111009 tokens, 224.3 tok/s, 42 s
[strata] answering: 8311 of max 111009 tokens, 224.6 tok/s, 43 s
[strata] answering: 8533 of max 111009 tokens, 224.4 tok/s, 44 s
[strata] answering: 8781 of max 111009 tokens, 225.0 tok/s, 45 s
[strata] answering: 9035 of max 111009 tokens, 225.6 tok/s, 46 s
[strata] answering: 9276 of max 111009 tokens, 225.9 tok/s, 47 s
[strata] answering: 9514 of max 111009 tokens, 226.2 tok/s, 48 s
[strata] answering: 9750 of max 111009 tokens, 226.4 tok/s, 49 s
[strata] answering: 9991 of max 111009 tokens, 226.6 tok/s, 50 s
[strata] answering: 10204 of max 111009 tokens, 226.3 tok/s, 51 s
[strata] answering: 10473 of max 111009 tokens, 227.2 tok/s, 52 s
[strata] answering: 10774 of max 111009 tokens, 228.7 tok/s, 53 s
[strata] answering: 11092 of max 111009 tokens, 230.5 tok/s, 54 s
[strata] answering: 11219 of max 111009 tokens, 228.2 tok/s, 56 s
[strata] answering: 11347 of max 111009 tokens, 226.1 tok/s, 57 s
[strata] answering: 11466 of max 111009 tokens, 223.8 tok/s, 58 s
[strata] answering: 11623 of max 111009 tokens, 222.5 tok/s, 59 s
[strata] answering: 11792 of max 111009 tokens, 221.5 tok/s, 60 s
[strata] done: 11963 tokens in 61 s (220.7 tok/s) (stop, cancel=False), expert cache 97.5% hit (+0.4% of the routed experts over PCIe)
[strata] reading the prompt: 8,192 of 47,318 tokens, 2 s so far
[strata] reading the prompt: 15,999 of 47,318 tokens, 4 s so far
[strata] reading the prompt: 24,191 of 47,318 tokens, 6 s so far
[strata] reading the prompt: 32,383 of 47,318 tokens, 8 s so far
[strata] reading the prompt: 40,575 of 47,318 tokens, 10 s so far
[strata] reading the prompt: 47,311 of 47,318 tokens, 12 s so far
[strata] writing a tool call: execute_code: 74 of max 65536 tokens, 131.7 tok/s, 13 s
[strata] writing a tool call: execute_code: 213 of max 65536 tokens, 135.2 tok/s, 14 s
[strata] done: 279 tokens in 14 s (140.9 tok/s) (stop, cancel=False), expert cache 91.8% hit (+2.3% of the routed experts over PCIe)
[strata] reading the prompt: 533 of 540 tokens, 1 s so far
[strata] done: 4 tokens in 1 s (199.9 tok/s) (stop, cancel=False), expert cache 92.8% hit (+1.3% of the routed experts over PCIe)
[strata] reading the prompt: 48,261 of 48,268 tokens, 1 s so far
[strata] writing a tool call: execute_code: 165 of max 65536 tokens, 178.7 tok/s, 2 s
[strata] done: 345 tokens in 3 s (181.4 tok/s) (stop, cancel=False), expert cache 96.6% hit (+0.8% of the routed experts over PCIe)
[strata] reading the prompt: 539 of 540 tokens, 1 s so far
[strata] done: 4 tokens in 1 s (87.8 tok/s) (stop, cancel=False), expert cache 95.0% hit (+0.7% of the routed experts over PCIe)
[strata] reading the prompt: 49,931 of 49,938 tokens, 2 s so far
[strata] writing a tool call: execute_code: 234 of max 65536 tokens, 276.4 tok/s, 3 s
[strata] done: 279 tokens in 3 s (264.4 tok/s) (stop, cancel=False), expert cache 98.1% hit (+0.3% of the routed experts over PCIe)
[strata] done: 4 tokens in 0 s (285.5 tok/s) (stop, cancel=False), expert cache 97.5% hit (+0.4% of the routed experts over PCIe)
[strata] reading the prompt: 50,881 of 50,888 tokens, 1 s so far
[strata] writing a tool call: execute_code: 215 of max 65536 tokens, 240.6 tok/s, 2 s
[strata] done: 345 tokens in 3 s (234.8 tok/s) (stop, cancel=False), expert cache 97.5% hit (+0.5% of the routed experts over PCIe)
[strata] done: 4 tokens in 0 s (145.3 tok/s) (stop, cancel=False), expert cache 97.2% hit (+0.5% of the routed experts over PCIe)
[strata] reading the prompt: 52,551 of 52,558 tokens, 2 s so far
[strata] writing a tool call: execute_code: 222 of max 65536 tokens, 262.8 tok/s, 3 s
[strata] done: 279 tokens in 3 s (255.8 tok/s) (stop, cancel=False), expert cache 98.0% hit (+0.3% of the routed experts over PCIe)
[strata] done: 4 tokens in 0 s (166.5 tok/s) (stop, cancel=False), expert cache 97.4% hit (+0.5% of the routed experts over PCIe)
[strata] reading the prompt: 53,501 of 53,508 tokens, 1 s so far
[strata] writing a tool call: execute_code: 233 of max 65536 tokens, 265.2 tok/s, 2 s
[strata] done: 345 tokens in 3 s (253.6 tok/s) (stop, cancel=False), expert cache 97.8% hit (+0.4% of the routed experts over PCIe)
[strata] done: 42 tokens in 1 s (71.5 tok/s) (stop, cancel=False), expert cache 92.2% hit (+1.8% of the routed experts over PCIe)
[strata] done: 4 tokens in 0 s (124.9 tok/s) (stop, cancel=False), expert cache 95.5% hit (+0.9% of the routed experts over PCIe)
[strata] reading the prompt: 55,171 of 55,178 tokens, 2 s so far
[strata] writing a tool call: execute_code: 210 of max 65536 tokens, 249.7 tok/s, 3 s
[strata] done: 279 tokens in 3 s (245.9 tok/s) (stop, cancel=False), expert cache 97.9% hit (+0.4% of the routed experts over PCIe)
[strata] done: 4 tokens in 0 s (257.9 tok/s) (stop, cancel=False), expert cache 97.2% hit (+0.4% of the routed experts over PCIe)
[strata] reading the prompt: 8,192 of 14,983 tokens, 2 s so far
[strata] reading the prompt: 14,976 of 14,983 tokens, 4 s so far
[strata] answering: 47 of max 116081 tokens, 76.8 tok/s, 5 s
[strata] answering: 171 of max 116081 tokens, 105.9 tok/s, 6 s
[strata] answering: 338 of max 116081 tokens, 127.6 tok/s, 7 s
[strata] answering: 534 of max 116081 tokens, 145.7 tok/s, 8 s
[strata] answering: 720 of max 116081 tokens, 152.5 tok/s, 9 s
[strata] answering: 947 of max 116081 tokens, 164.4 tok/s, 10 s
[strata] answering: 1116 of max 116081 tokens, 165.1 tok/s, 11 s
[strata] answering: 1333 of max 116081 tokens, 171.4 tok/s, 12 s
answering: 38580 of max 116081 tokens, 302.0 tok/s, 132 s
[strata] answering: 38904 of max 116081 tokens, 302.2 tok/s, 133 s
[strata] answering: 39210 of max 116081 tokens, 302.2 tok/s, 134 s
[strata] answering: 39528 of max 116081 tokens, 302.3 tok/s, 135 s
[strata] answering: 39840 of max 116081 tokens, 302.3 tok/s, 136 s
[strata] answering: 40164 of max 116081 tokens, 302.5 tok/s, 137 s
[strata] answering: 40482 of max 116081 tokens, 302.6 tok/s, 138 s
[strata] answering: 40804 of max 116081 tokens, 302.7 tok/s, 139 s
[strata] answering: 41124 of max 116081 tokens, 302.8 tok/s, 140 s
[strata] answering: 41442 of max 116081 tokens, 302.9 tok/s, 141 s
[strata] answering: 41772 of max 116081 tokens, 303.1 tok/s, 142 s
[strata] answering: 42096 of max 116081 tokens, 303.2 tok/s, 143 s
[strata] answering: 42420 of max 116081 tokens, 303.4 tok/s, 144 s
[strata] answering: 42738 of max 116081 tokens, 303.5 tok/s, 145 s
[strata] answering: 43058 of max 116081 tokens, 303.6 tok/s, 146 s
[strata] answering: 43374 of max 116081 tokens, 303.6 tok/s, 147 s
[strata] answering: 43696 of max 116081 tokens, 303.7 tok/s, 148 s
[strata] answering: 44016 of max 116081 tokens, 303.8 tok/s, 149 s
[strata] answering: 44322 of max 116081 tokens, 303.8 tok/s, 150 s
[strata] answering: 44628 of max 116081 tokens, 303.8 tok/s, 151 s
...我估计短上下文的估计可行,但遇到长上下文就不行了。 就在这里无止境的循环了。
@tester12340
发一个我48GB 的 rtx pro 5000的全套参数给你参考,你根据自己内存大小调整。"args": [ "--pack", "C:\\work\\Strata-data\\packs\\iq3_xxs", "--native", "C:\\work\\Strata-data\\models\\IQ3_XXS\\Qwen3.8-Flash-Next-GSQ-RCO-IQ3_XXS-00001-of-00002.gguf", "--ple-gguf", "C:\\work\\Strata-data\\models\\IQ3_XXS\\Qwen3.8-Flash-Next-GSQ-RCO-IQ3_XXS-00002-of-00002.gguf", "--expert-profile", "C:\\work\\Strata\\data\\expert-profile.bin", "--resident-experts", "--expert-cache", "19000", "--prefill", "auto", "--spec", "4", "--mtp", "C:\\work\\Strata-data\\mtp\\rt", "--max-context", "262144", "--kv", "k8v4", "--vision", "--vram-reserve-mib", "3400", "--pcie-frac", "0.00", "--spec-min-p", "0.70", "--conversation-cache-mib", "27648", "--conversation-cache-slots", "9", "--conversation-cache-min-free-mib", "8192", "--prompt-cache-every", "8192" ], -
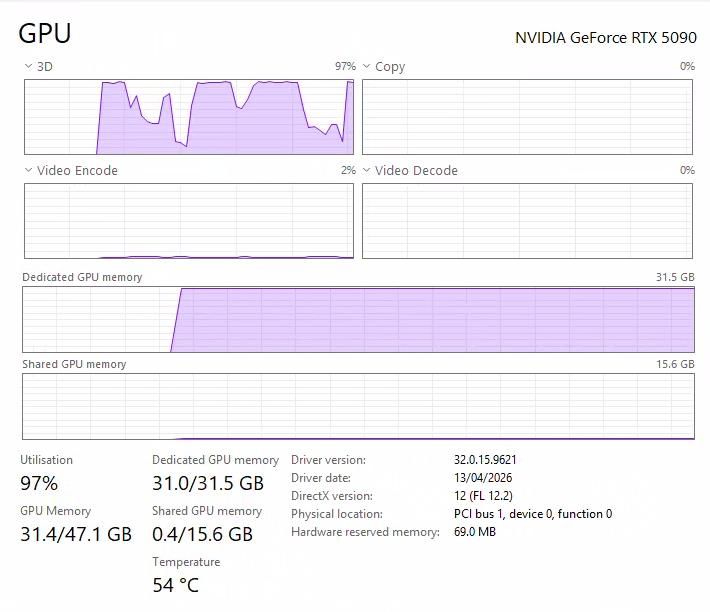
跟我逾期的一样。就是短上下文没问题。但长上下文就会进入无尽的循环。 然后还会自动降级到 65535 。 32gb已经被榨干。我想是 32gb 就是老黄这个奸商设计的短板吧。 还是 48g香啊
trata] reading the prompt: 1,024 of 1,031 tokens, 3 s so far
[strata] done: 4 tokens in 3 s (56.3 tok/s) (stop, cancel=False), expert cache 56.0% hit
[strata] reading the prompt: 8,192 of 8,975 tokens, 3 s so far
[strata] reading the prompt: 8,968 of 8,975 tokens, 5 s so far
[strata] answering: 40 of max 122089 tokens, 95.7 tok/s, 6 s
[strata] answering: 163 of max 122089 tokens, 111.8 tok/s, 7 s
[strata] answering: 287 of max 122089 tokens, 114.3 tok/s, 8 s
[strata] answering: 418 of max 122089 tokens, 117.5 tok/s, 9 s
[strata] answering: 572 of max 122089 tokens, 125.2 tok/s, 10 s
[strata] answering: 717 of max 122089 tokens, 128.6 tok/s, 11 s
[strata] answering: 842 of max 122089 tokens, 127.8 tok/s, 12 s
[strata] answering: 1000 of max 122089 tokens, 131.5 tok/s, 13 s
[strata] answering: 1161 of max 122089 tokens, 134.9 tok/s, 14 s
[strata] answering: 1344 of max 122089 tokens, 139.9 tok/s, 15 s
[strata] answering: 1497 of max 122089 tokens, 140.9 tok/s, 16 s
[strata] answering: 1658 of max 122089 tokens, 142.5 tok/s, 17 s
[strata] answering: 1817 of max 122089 tokens, 143.7 tok/s, 18 s
[strata] answering: 1981 of max 122089 tokens, 145.1 tok/s, 19 s
[strata] answering: 2164 of max 122089 tokens, 147.5 tok/s, 20 s
[strata] answering: 2309 of max 122089 tokens, 146.7 tok/s, 21 s
[strata] thinking: 19 of max 130783 tokens, 41.2 tok/s, 1 s
[strata] answering: 2337 of max 122089 tokens, 139.4 tok/s, 23 s
[strata] answering: 77 of max 130783 tokens, 52.2 tok/s, 2 s
[strata] done: 82 tokens in 2 s (52.4 tok/s) (stop, cancel=False), expert cache 59.8% hit
[strata] answering: 2394 of max 122089 tokens, 133.5 tok/s, 24 s
[strata] answering: 2553 of max 122089 tokens, 134.8 tok/s, 25 s
[strata] answering: 2713 of max 122089 tokens, 135.9 tok/s, 26 s
[strata] answering: 2879 of max 122089 tokens, 137.2 tok/s, 27 s
[strata] answering: 3050 of max 122089 tokens, 138.6 tok/s, 28 s
[strata] answering: 3236 of max 122089 tokens, 140.6 tok/s, 29 s
[strata] answering: 3414 of max 122089 tokens, 142.0 tok/s, 30 s
[strata] answering: 3588 of max 122089 tokens, 143.2 tok/s, 31 s
[strata] answering: 3783 of max 122089 tokens, 145.1 tok/s, 32 s
[strata] answering: 3975 of max 122089 tokens, 146.8 tok/s, 33 s
[strata] answering: 4161 of max 122089 tokens, 148.2 tok/s, 34 s
[strata] answering: 4344 of max 122089 tokens, 149.3 tok/s, 35 s
[strata] answering: 4543 of max 122089 tokens, 150.9 tok/s, 36 s
[strata] answering: 4755 of max 122089 tokens, 152.7 tok/s, 37 s
[strata] answering: 4927 of max 122089 tokens, 153.2 tok/s, 38 s
[strata] answering: 5113 of max 122089 tokens, 154.0 tok/s, 39 s
[strata] done: 5184 tokens in 39 s (154.4 tok/s) (stop, cancel=False), expert cache 90.8% hit
[strata] reading the prompt: 24,186 of 52,038 tokens, 3 s so far
[strata] reading the prompt: 32,378 of 52,038 tokens, 6 s so far
[strata] reading the prompt: 40,570 of 52,038 tokens, 9 s so far
[strata] reading the prompt: 48,762 of 52,038 tokens, 12 s so far
[strata] reading the prompt: 52,031 of 52,038 tokens, 15 s so far
[strata] writing a tool call: execute_code: 48 of max 65536 tokens, 111.8 tok/s, 16 s
[strata] writing a tool call: execute_code: 180 of max 65536 tokens, 125.3 tok/s, 17 s
[strata] writing a tool call: execute_code: 330 of max 65536 tokens, 134.9 tok/s, 18 s
[strata] writing a tool call: execute_code: 478 of max 65536 tokens, 138.1 tok/s, 19 s
[strata] writing a tool call: execute_code: 655 of max 65536 tokens, 146.7 tok/s, 20 s
[strata] writing a tool call: execute_code: 807 of max 65536 tokens, 147.1 tok/s, 21 s
[strata] done: 846 tokens in 22 s (146.3 tok/s) (stop, cancel=False), expert cache 84.5% hit
[strata] reading the prompt: 1,030 of 1,037 tokens, 3 s so far
[strata] done: 4 tokens in 3 s (57.1 tok/s) (stop, cancel=False), expert cache 60.8% hit
[strata] reading the prompt: 8,192 of 53,028 tokens, 3 s so far
[strata] reading the prompt: 15,994 of 53,028 tokens, 6 s so far
[strata] reading the prompt: 24,186 of 53,028 tokens, 9 s so far
[strata] reading the prompt: 32,378 of 53,028 tokens, 12 s so far
[strata] reading the prompt: 40,570 of 53,028 tokens, 15 s so far
[strata] reading the prompt: 48,762 of 53,028 tokens, 18 s so far
[strata] reading the prompt: 53,021 of 53,028 tokens, 21 s so far
[strata] writing a tool call: execute_code: 60 of max 65536 tokens, 135.5 tok/s, 22 s
[strata] writing a tool call: execute_code: 235 of max 65536 tokens, 162.1 tok/s, 23 s
[strata] writing a tool call: execute_code: 428 of max 65536 tokens, 174.2 tok/s, 24 s
[strata] writing a tool call: execute_code: 622 of max 65536 tokens, 179.3 tok/s, 25 s
[strata] writing a tool call: execute_code: 795 of max 65536 tokens, 177.8 tok/s, 26 s
[strata] done: 852 tokens in 26 s (176.2 tok/s) (stop, cancel=False), expert cache 90.0% hit
[strata] reading the prompt: 1,036 of 1,043 tokens, 3 s so far
[strata] done: 4 tokens in 3 s (53.6 tok/s) (stop, cancel=False), expert cache 60.1% hit
[strata] reading the prompt: 8,192 of 54,024 tokens, 3 s so far
[strata] reading the prompt: 15,994 of 54,024 tokens, 6 s so far
[strata] reading the prompt: 24,186 of 54,024 tokens, 9 s so far
[strata] reading the prompt: 32,378 of 54,024 tokens, 12 s so far
[strata] reading the prompt: 40,570 of 54,024 tokens, 15 s so far
[strata] reading the prompt: 48,762 of 54,024 tokens, 18 s so far
[strata] reading the prompt: 54,017 of 54,024 tokens, 21 s so far
-
-
-
,T tester12340 将此主题交叉发布至 LLM讨论区
-
无论怎么折腾,遇到长下文直接崩掉。。从来。
大神们,我还有啥能做的吗? -
感谢,测试了。我感觉是可以了。 我再测试一下。
两个并行,单个能跑到 200 tok每秒
writing a tool call: execute_code: 816 of max 65536 tokens, 215.0 tok/s, 6 s
[strata] done: 944 tokens in 6 s (216.2 tok/s) (stop, cancel=False), expert cache 97.5% hit感谢peter!
[strata] reading the prompt: 47,058 of 47,065 tokens, 2 s so far
[strata] answering: 137 of max 65536 tokens, 176.2 tok/s, 3 s
[strata] answering: 322 of max 65536 tokens, 180.1 tok/s, 4 s
[strata] writing a tool call: execute_code: 560 of max 65536 tokens, 200.3 tok/s, 5 s
[strata] writing a tool call: execute_code: 783 of max 65536 tokens, 205.9 tok/s, 6 sstara 现在这么牛逼 感觉那些小主机全没用了啊
-
为论坛做贡献,分享一下 5090 目前配置 stara 跑 next 的配置。 感谢 Peter 和 各位大神的指点。感谢锤子提供这么好的论坛。
{
"exe": "C:\strata\Strata\engine\strata.exe",
"args": [
"--pack",
"C:\strata\Strata-data\packs\q2_0",
"--native",
"C:\strata\Strata-data\models\Q2_0\Qwen3.8-Flash-Next-GSQ-RCO-Q2_0-00001-of-00002.gguf",
"--ple-gguf",
"C:\strata\Strata-data\models\Q2_0\Qwen3.8-Flash-Next-GSQ-RCO-Q2_0-00002-of-00002.gguf",
"--expert-profile",
"C:\strata\Strata\data\expert-profile.bin",
"--expert-cache",
"auto",
"--prefill",
"auto",
"--spec",
"4",
"--mtp",
"C:\strata\Strata-data\mtp\rt",
"--max-context",
"131072",
"--kv","q4_0",
"--kv-resident","32768",
"--vram-reserve-mib","700",
"--resident-experts",
"--pcie-frac",
"0.35",
"--spec-min-p",
"0.50",
"--pool-workers",
"4","--conversation-cache-mib", "8192"
],
"cwd": "C:\strata\Strata",
"parallel": 4,
"tokenizer": "C:\strata\Strata-data\packs\q2_0\tokenizer",
"model_name": "qwen3.8-flash-next-q2_0",
"log": "C:\strata\Strata\strata-q2_0.log",
"lib_dirs": [
"C:\strata\Strata\.venv\Lib\site-packages\nvidia\cu13\bin\x86_64"
],
"host":"192.168.0.3",
"port": 8080,
"gpu": 0,
"gpus_asked": true
}有需要优化的地方 请大家指正。
另外默默问一句, mac ultra 96 是不是会完败 5090 staraa?
-
-
-
-
-
为论坛做贡献,分享一下 5090 目前配置 stara 跑 next 的配置。 感谢 Peter 和 各位大神的指点。感谢锤子提供这么好的论坛。
{
"exe": "C:\strata\Strata\engine\strata.exe",
"args": [
"--pack",
"C:\strata\Strata-data\packs\q2_0",
"--native",
"C:\strata\Strata-data\models\Q2_0\Qwen3.8-Flash-Next-GSQ-RCO-Q2_0-00001-of-00002.gguf",
"--ple-gguf",
"C:\strata\Strata-data\models\Q2_0\Qwen3.8-Flash-Next-GSQ-RCO-Q2_0-00002-of-00002.gguf",
"--expert-profile",
"C:\strata\Strata\data\expert-profile.bin",
"--expert-cache",
"auto",
"--prefill",
"auto",
"--spec",
"4",
"--mtp",
"C:\strata\Strata-data\mtp\rt",
"--max-context",
"131072",
"--kv","q4_0",
"--kv-resident","32768",
"--vram-reserve-mib","700",
"--resident-experts",
"--pcie-frac",
"0.35",
"--spec-min-p",
"0.50",
"--pool-workers",
"4","--conversation-cache-mib", "8192"
],
"cwd": "C:\strata\Strata",
"parallel": 4,
"tokenizer": "C:\strata\Strata-data\packs\q2_0\tokenizer",
"model_name": "qwen3.8-flash-next-q2_0",
"log": "C:\strata\Strata\strata-q2_0.log",
"lib_dirs": [
"C:\strata\Strata\.venv\Lib\site-packages\nvidia\cu13\bin\x86_64"
],
"host":"192.168.0.3",
"port": 8080,
"gpu": 0,
"gpus_asked": true
}有需要优化的地方 请大家指正。
另外默默问一句, mac ultra 96 是不是会完败 5090 staraa?
-
按terry 老板要求
{
"exe": "C:\strata\Strata\engine\strata.exe",
"args": [
"--pack",
"C:\strata\Strata-data\packs\q2_0",
"--native",
"C:\strata\Strata-data\models\Q2_0\Qwen3.8-Flash-Next-GSQ-RCO-Q2_0-00001-of-00002.gguf",
"--ple-gguf",
"C:\strata\Strata-data\models\Q2_0\Qwen3.8-Flash-Next-GSQ-RCO-Q2_0-00002-of-00002.gguf",
"--expert-profile",
"C:\strata\Strata\data\expert-profile.bin",
"--expert-cache",
"auto",
"--prefill",
"auto",
"--spec",
"4",
"--mtp",
"C:\strata\Strata-data\mtp\rt",
"--max-context",
"131072",
"--kv",
"q4_0",
"--kv-resident",
"32768",
"--vram-reserve-mib",
"700",
"--resident-experts",
"--pcie-frac",
"0.35",
"--spec-min-p",
"0.50",
"--pool-workers",
"4",
"--conversation-cache-mib",
"8192"
],
"cwd": "C:\strata\Strata",
"parallel": 4,
"tokenizer": "C:\strata\Strata-data\packs\q2_0\tokenizer",
"model_name": "qwen3.8-flash-next-q2_0",
"log": "C:\strata\Strata\strata-q2_0.log",
"lib_dirs": [
"C:\strata\Strata\.venv\Lib\site-packages\nvidia\cu13\bin\x86_64"
],
"host": "192.168.0.3",
"port": 8080,
"gpu": 0,
"gpus_asked": true
}这个对了吗?
-
-
-
-
-
-