
请教各位大神,5090 上 stara 如何支持多线程能快点啊?
-
-
@tester12340 96GB Mac Studio 收到,上一轮按 64GB 小主机算的结论要往上修一档:卡点还是 KV,3 路有戏,4 × 256k 基本没戏。
按 27B 常见 GQA(约 64 层、8 个 KV head)估:FP16 KV ≈ 0.25MB/token,8bit ≈ 0.125,4bit ≈ 0.06。
- 单路 256k:FP16 ~64GB / 8bit ~32GB / 4bit ~16GB
- 3 路 256k:FP16 192GB(✗)/ 8bit 96GB KV + 28GB 权重 ≈ 124GB(✗)/ 4bit 48GB + 28GB ≈ 76GB(✓ 但很紧)
- 4 路 256k 8bit:128GB KV + 28GB 权重,96GB 装不下
能落地的档位:
- 3 × 128k + KV 8bit:48 + 28 ≈ 76GB,紧但能跑
- 3 × 64k + KV 8bit:24 + 28 ≈ 52GB,舒服 —— 我推荐这档
- 非要 3 × 256k,只能 KV 压 4bit,质量和 TTFT 都会掉,不划算
要「并发 + 量化 KV」别用 mlx-lm 的
--kv-bits:官方 help 明写开了它会 disables batching,退化成一次只服务一条。用 llama.cpp:llama-server -m qwen3-27b-Q8_0.gguf -fa on -ctk q8_0 -ctv q8_0 -np 3 --kv-unified-per-slot 131072(3 路各 128k;改成
65536就是各 64k。KV 量化必须配-fa。)两个现实提醒:
- macOS 默认给 GPU 的 wired 上限约内存 75%(96GB → ~72GB),跑 76GB 那档得用
sudo sysctl iogpu.wired_limit_mb=抬一点,别顶满,留 8~10GB 给系统。 - 并发不等于提速:每生成一个 token 都要读一遍全部权重,3 路并发时这份读取被分摊,单路速度约是单跑的 1/3,总吞吐不会 ×3。真嫌慢就把 per-slot 上下文按实际需要调小,别硬留 256k。
到货后把机型和
llama-server启动日志发上来,按实际模型 config 正式算一遍。 -
-
@haia-m 看你说的 Q6_K 是哪一层,答案不一样:
1)KV cache 用 Q6_K —— 没这个档。 llama.cpp 的
-ctk/-ctv只认f32/f16/bf16/q8_0/q4_0/q4_1/iq4_nl/q5_0/q5_1,填 Q6_K 会直接报错退出。想在 8bit 和 4bit 之间找中间档,用q5_1;更稳的做法是 K 保 q8_0、只压 V(K 量化更伤注意力)。KV 量化必须配-fa on。2)权重用 Q6_K(GGUF 量化档)—— 合法。 约 6.56 bit/权重,27B 约 22GB,比 Q8_0 的 ~28-29GB 省 6-7GB。
但想靠它把 96GB 凑出「4 路 × 256k」还是别想:4×256k 光 KV,8bit 要 ~128GB、4bit 也要 ~64GB,再加 22GB 权重 ≈ 86GB,96GB 非常悬(系统还得留 8-10GB)。3 路是现实档:
- 3×256k + KV q8_0 ≈ 96+22GB ✗
- 3×256k + KV q4_0 ≈ 48+22 ≈ 70GB ✓(很紧,q4 KV 长上下文掉质量)
- 3×128k + KV q8_0 ≈ 48+22 ≈ 70GB ✓
- 3×64k + KV q8_0 ≈ 24+22 ≈ 46GB ✓ 最稳
起服务(3 路各 128k):
llama-server -m qwen3-27b-Q6_K.gguf -fa on -ctk q8_0 -ctv q8_0 -np 3 --kv-unified-per-slot 131072先
sudo sysctl iogpu.wired_limit_mb=给 GPU 抬上限,别顶满,留 8-10GB 给系统。到货把启动日志发上来,按实际 config 再算一遍。 -
5090 128gb ddr5 + nvme 99pro
都知道 stara很香,不过这个换个线程基本等到头发都掉了。自己玩玩还行,一旦hermes 开多agents 就完蛋了。
请问各位大神有什么办法提高预加载或者多线程的速度么?
@tester12340 换strata nvfp4,https://github.com/sergqwer/strata-nvfp4,跑nvfp4版的flash next,官方的方案和你这个硬件是一摸一样的。至于多线程,说实话,你这个硬件的显存就这么多,才32g,高并发就不是给你准备的,你的速度到170tps就满了,分多少都是这个天花板。
-
@roid-isis 感谢回复。 我问的是 mac m5 ultra 96gb
-
@haia-m @roid-isis 是给我的回复
-
按terry 老板要求
{
"exe": "C:\strata\Strata\engine\strata.exe",
"args": [
"--pack",
"C:\strata\Strata-data\packs\q2_0",
"--native",
"C:\strata\Strata-data\models\Q2_0\Qwen3.8-Flash-Next-GSQ-RCO-Q2_0-00001-of-00002.gguf",
"--ple-gguf",
"C:\strata\Strata-data\models\Q2_0\Qwen3.8-Flash-Next-GSQ-RCO-Q2_0-00002-of-00002.gguf",
"--expert-profile",
"C:\strata\Strata\data\expert-profile.bin",
"--expert-cache",
"auto",
"--prefill",
"auto",
"--spec",
"4",
"--mtp",
"C:\strata\Strata-data\mtp\rt",
"--max-context",
"131072",
"--kv",
"q4_0",
"--kv-resident",
"32768",
"--vram-reserve-mib",
"700",
"--resident-experts",
"--pcie-frac",
"0.35",
"--spec-min-p",
"0.50",
"--pool-workers",
"4",
"--conversation-cache-mib",
"8192"
],
"cwd": "C:\strata\Strata",
"parallel": 4,
"tokenizer": "C:\strata\Strata-data\packs\q2_0\tokenizer",
"model_name": "qwen3.8-flash-next-q2_0",
"log": "C:\strata\Strata\strata-q2_0.log",
"lib_dirs": [
"C:\strata\Strata\.venv\Lib\site-packages\nvidia\cu13\bin\x86_64"
],
"host": "192.168.0.3",
"port": 8080,
"gpu": 0,
"gpus_asked": true
}这个对了吗?
今天請我家AI抄作業,抄好後發現
parallel": 4....這數字我只要設1以上,併發都會模型重啟
非常不穩定
還是說這問題只發生在雙卡?
下面是我的參數
{
"exe": "/home/alpha/strata-nvfp4/engine/strata",
"args": [
"--pack",
"/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/pack",
"--native",
"/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/qwen-nvfp4-gptq-dense.gguf",
"--native-dense-gguf",
"/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/qwen-nvfp4-gptq-dense.gguf",
"--ple-gguf",
"/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/ple-fp8.gguf",
"--embd-gguf",
"/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/token-embd-bf16.gguf",
"--expert-profile",
"/home/alpha/strata-nvfp4/data/expert-profile.bin",
"--expert-cache",
"auto",
"--prefill",
"8192",
"--spec",
"6",
"--spec-min-p",
"0.7",
"--mtp",
"/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/mtp",
"--max-context",
"163840",
"--kv",
"k8v4",
"--vram-reserve-mib",
"960",
"--control-vector-scaled",
"/home/alpha/strata-nvfp4/data/uncensor/qwen-nvfp4-gptq-uncensored.gguf:1.0",
"--control-vector-layer-range",
"8",
"33",
"--cvec-mode",
"project",
"--cvec-dir",
"per-layer",
"--conversation-cache-mib",
"4096",
"--mmap-experts",
"--pool-workers",
"31"
],
"cwd": "/home/alpha/strata-nvfp4",
"tokenizer": "/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/pack/tokenizer",
"model_name": "qwen38-nvfp4-mtp",
"log": "/home/alpha/strata-nvfp4/strata-qwen-gptq-nvfp4.log",
"lib_dirs": [
"/usr/local/cuda-13.0/bin",
"/usr/local/cuda-13.0/lib64"
],
"port": 8080,
"gpu": [
0,
1
],
"gpus_asked": true,
"sampling": {
"temperature": 1.0,
"top_p": 0.95,
"top_k": 20
},
"uncensored": false,
"layer_split": "auto",
"parallel": 1,
"vision": {
"exe": "/home/alpha/strata-nvfp4/engine/strata-vision",
"model": "/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/qwen-nvfp4-gptq-dense.gguf",
"mmproj": "/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/mmproj-Qwen3.8-Flash-Next-BF16.gguf",
"min_tokens": 1024,
"max_tokens": 1024
}
} -
今天請我家AI抄作業,抄好後發現
parallel": 4....這數字我只要設1以上,併發都會模型重啟
非常不穩定
還是說這問題只發生在雙卡?
下面是我的參數
{
"exe": "/home/alpha/strata-nvfp4/engine/strata",
"args": [
"--pack",
"/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/pack",
"--native",
"/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/qwen-nvfp4-gptq-dense.gguf",
"--native-dense-gguf",
"/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/qwen-nvfp4-gptq-dense.gguf",
"--ple-gguf",
"/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/ple-fp8.gguf",
"--embd-gguf",
"/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/token-embd-bf16.gguf",
"--expert-profile",
"/home/alpha/strata-nvfp4/data/expert-profile.bin",
"--expert-cache",
"auto",
"--prefill",
"8192",
"--spec",
"6",
"--spec-min-p",
"0.7",
"--mtp",
"/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/mtp",
"--max-context",
"163840",
"--kv",
"k8v4",
"--vram-reserve-mib",
"960",
"--control-vector-scaled",
"/home/alpha/strata-nvfp4/data/uncensor/qwen-nvfp4-gptq-uncensored.gguf:1.0",
"--control-vector-layer-range",
"8",
"33",
"--cvec-mode",
"project",
"--cvec-dir",
"per-layer",
"--conversation-cache-mib",
"4096",
"--mmap-experts",
"--pool-workers",
"31"
],
"cwd": "/home/alpha/strata-nvfp4",
"tokenizer": "/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/pack/tokenizer",
"model_name": "qwen38-nvfp4-mtp",
"log": "/home/alpha/strata-nvfp4/strata-qwen-gptq-nvfp4.log",
"lib_dirs": [
"/usr/local/cuda-13.0/bin",
"/usr/local/cuda-13.0/lib64"
],
"port": 8080,
"gpu": [
0,
1
],
"gpus_asked": true,
"sampling": {
"temperature": 1.0,
"top_p": 0.95,
"top_k": 20
},
"uncensored": false,
"layer_split": "auto",
"parallel": 1,
"vision": {
"exe": "/home/alpha/strata-nvfp4/engine/strata-vision",
"model": "/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/qwen-nvfp4-gptq-dense.gguf",
"mmproj": "/home/alpha/Strata-data/models/Maximilian228--Qwen3.8-Flash-Next-NVFP4-GPTQ-Strata/mmproj-Qwen3.8-Flash-Next-BF16.gguf",
"min_tokens": 1024,
"max_tokens": 1024
}
}@David-Chen 我这也是极其不稳定。 只有降了精度之后才能稳定一些。 我感觉是 strata 在多线程的使用的时候 在什么地方没有限制好,导致内存溢出而崩溃。 降级之后会好一些,你试试看。
-
@david-chen 这么说吧 5090 下我开4个session,平时也就是2个同时跑的情况下。 Q2 勉强可以用。Q2 以上什么都直接卡死。
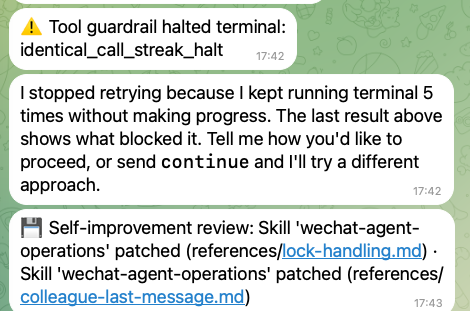
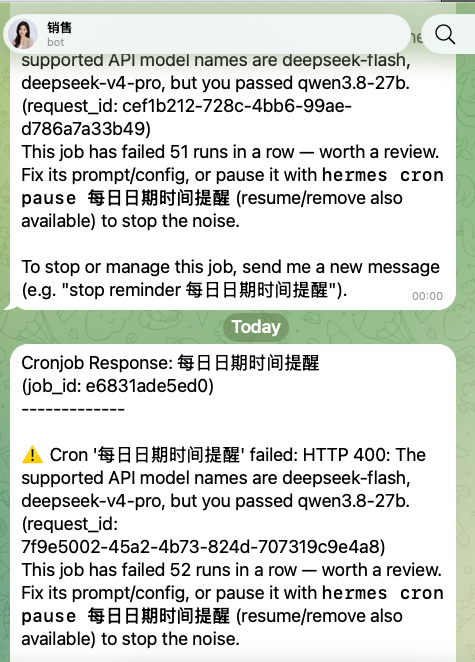
我现在 Q2 的时候 还经常这样。
-
-
买两块r9700 来试试?

-
-
@applejuice 没钱啊 ε=(´ο`*)))唉,我在等最低端 mac 小主机。 希望能当生产环境用。
@tester12340 你可以參考這文章 https://lcz.me/topic/2404
並行跑是不會有問題的
但這方案缺點是- 目前只支援單卡
- df2還沒出來
- nvfp4 v2 還沒支援
但是整個效率如何,就看妳實際需求了
以下是我壓力測試的數據
!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!(我用的模型是nvfp4 不是 iq2 iq3那種)!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!1分數表
v2/v3(YaRN 2×, max-context 512K, pending-timeout 默認 30s)
關卡 存活 Prefill/stream Decode/stream TTFT 最差 32K×4 4/4 5.0–5.5k 34–67 35.7s 64K×4 3/4 (1×503) 5.5–6.1k 60–67 35.4s 128K×4 2/4→3/4* 6.2–6.8k 125–214* 63.1s 192K×4 1/4 4.80k 69.3 44.0s 256K×4 1/4 5.05k 105.9 53.6s 384K×4 1/4 5.62k 206.1* 70.4s * 數數任務 MTP 接受率≈100% 灌水;真實工作 decode 參考帶 50–120 tok/s(自己 session 的 tool-calls 流量實測)。
v5(YaRN 4×, max-context 1M, pending-timeout 180s)★修正後基準
關卡 存活 Prefill/stream Decode/stream Decode 合計(×4) TTFT 疊加曲線 批次牆鐘 Batch aggregate 128K×4 4/4 
4.95–6.38k 56–67 ~234 28→85→86→107s 113.3s ~10.3 tok/s 256K×4 4/4 5.94–6.87k 99–152 ~562* 44→129→131→170s 174.0s ~6.7 tok/s * 含灌水;req#10 中途中 stop token 只出 21 tokens,樣本有雜訊。
v6 thinking OFF vs LOW(同 prompt seed、128K/256K×4)
關卡 存活 OFF→LOW Prefill/stream OFF→LOW Decode/stream OFF→LOW TTFT(最差) OFF→LOW 128K×4 4/4→4/4 4.95–6.38k→4.02–5.33k 56–67→38.5–64.0 107s→134s 256K×4 4/4→4/4 5.94–6.87k→4.79–6.03k 99–152→54.6–195.7 170s→218s -
@david-chen 这看起来太牛了 感谢,今天就跑起来。
-
-
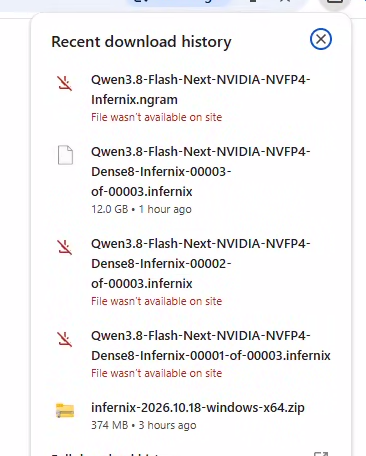
折腾很多次了。 我不折腾了,心累了。
@tester12340 你是不是沒拜拜^_^ 我昨天都還可以裝
-
@david-chen 今天早晨开始下,一开始速度很快能到 130mbps,后来就频繁断线。 反复重连。 算了 我还是再忍忍,或许等等他们再成熟成熟。 回头我想把5090 还是玩VR吧 O(∩_∩)O哈哈~
-
loading the model (the first start takes a minute or two) ...
[strata] starting the engine: reading the model's weights ...
[strata] loading the experts the GPU does not hold into RAM (of about 38 GB) and locking part of them for the GPU.
         YOUR PC CAN BE SLOW OR STOP RESPONDING FOR 1-3 MINUTES NOW - this is normal.
         Please wait and don't close this window; the browser opens when it is ready.
[strata] filling the GPU's expert cache (17148 experts, 22.08 GiB of VRAM) ...
[strata] still starting (24 s) - please wait ...
[strata] almost ready ...
ready: http://192.168.0.3:8080/v1  (OpenAI: /v1/chat/completions, Anthropic: /v1/messages, context 131072 tokens)
       open http://192.168.0.3:8080/ in a browser to chat; close this window to stop the model
       from other devices: http://192.168.0.3:8080/   (API: http://192.168.0.3:8080/v1)
       from other devices: http://172.23.128.1:8080/   (API: http://172.23.128.1:8080/v1)
       WARNING: no API key - anyone on your network can use this model. Add "api_key": "..." to the config (clients send it as their API key; the web page asks for it)
       nothing arrives? Windows Firewall blocks it until allowed: accept its prompt for Python, or run in an admin PowerShell:
         New-NetFirewallRule -DisplayName "Strata 8080" -Direction Inbound -Protocol TCP -LocalPort 8080 -Action Allow -Profile Private
       (and set this network to Private in Windows' network settings)
[strata] reading the prompt: 8,192 of 27,533 tokens, 2 s so far
[strata] reading the prompt: 16,384 of 27,533 tokens, 5 s so far
[strata] reading the prompt: 24,904 of 27,533 tokens, 8 s so far
[strata] reading the prompt: 27,526 of 27,533 tokens, 10 s so far
[strata] writing a tool call: terminal: 44 of max 103531 tokens, 113.9 tok/s, 11 s
[strata] done: 131 tokens in 12 s (117.8 tok/s) (stop, cancel=False), expert cache 85.4% hit
[strata] reading the prompt: 8,192 of 17,916 tokens, 2 s so far
[strata] reading the prompt: 16,003 of 17,916 tokens, 5 s so far
[strata] reading the prompt: 17,909 of 17,916 tokens, 6 s so far
[strata] reading the prompt: 27,960 of 27,967 tokens, 3 s so far
[strata] reading the prompt: 4 of max 65536 tokens, 2.6 tok/s, 9 s
[strata] writing a tool call: terminal: 52 of max 103097 tokens, 60.5 tok/s, 4 s
[strata] writing a tool call: execute_code: 79 of max 65536 tokens, 30.8 tok/s, 10 s
[strata] writing a tool call: terminal: 126 of max 103097 tokens, 67.4 tok/s, 5 s
[strata] writing a tool call: execute_code: 153 of max 65536 tokens, 42.8 tok/s, 11 s
[strata] done: 159 tokens in 5 s (68.2 tok/s) (stop, cancel=False), expert cache 97.3% hit
[strata] done: 171 tokens in 11 s (42.5 tok/s) (stop, cancel=False), expert cache 88.2% hit
[strata] done: 4 tokens in 1 s (70.1 tok/s) (stop, cancel=False), expert cache 94.9% hit
[strata] reading the prompt: 19,121 of 19,128 tokens, 2 s so far
[strata] writing a tool call: execute_code: 105 of max 65536 tokens, 128.7 tok/s, 3 s
[strata] done: 185 tokens in 3 s (150.5 tok/s) (stop, cancel=False), expert cache 96.6% hit
[strata] reading the prompt: 27,504 of 32,319 tokens, 2 s so far
[strata] reading the prompt: 32,312 of 32,319 tokens, 4 s so far
[strata] reading the prompt: 28,256 of 28,263 tokens, 5 s so far
[strata] reading the prompt: 4 of max 65536 tokens, 2.9 tok/s, 6 s
[strata] writing a tool call: terminal: 59 of max 102801 tokens, 67.2 tok/s, 6 s
[strata] done: 79 tokens in 6 s (69.7 tok/s) (stop, cancel=False), expert cache 95.8% hit
[strata] writing a tool call: execute_code: 85 of max 65536 tokens, 32.1 tok/s, 7 s
[strata] writing a tool call: search_files: 205 of max 65536 tokens, 48.9 tok/s, 9 s
[strata] answering: 20 of max 102682 tokens, 49.5 tok/s, 1 s
[strata] done: 223 tokens in 9 s (50.4 tok/s) (stop, cancel=False), expert cache 97.9% hit
[strata] reading the prompt: 485 of 486 tokens, 1 s so far
[strata] answering: 34 of max 102682 tokens, 17.6 tok/s, 3 s
[strata] done: 4 tokens in 1 s (35.3 tok/s) (stop, cancel=False), expert cache 98.3% hit
[strata] reading the prompt: 475 of 476 tokens, 1 s so far
[strata] answering: 80 of max 102682 tokens, 22.4 tok/s, 4 s
[strata] done: 4 tokens in 1 s (35.6 tok/s) (stop, cancel=False), expert cache 99.2% hit
[strata] answering: 124 of max 102682 tokens, 25.1 tok/s, 6 s
[strata] done: 4 tokens in 1 s (28.7 tok/s) (stop, cancel=False), expert cache 99.4% hit
[strata] done: 176 tokens in 6 s (32.6 tok/s) (stop, cancel=False), expert cache 97.1% hit
[strata] response_format json_schema: the Python package jsonschema is not installed, so answers are only checked to be one JSON object (python -m pip install "jsonschema>=4.23,<5")
[strata] reading the prompt: 844 of 851 tokens, 1 s so far
[strata] reading the prompt: 8,192 of 33,834 tokens, 3 s so far
[strata] answering: 4 of max 130213 tokens, 1.8 tok/s, 3 s
[strata] done: 11 tokens in 4 s (4.8 tok/s) (stop, cancel=False), expert cache 98.5% hit
[strata] reading the prompt: 16,003 of 33,834 tokens, 6 s so far
[strata] reading the prompt: 24,195 of 33,834 tokens, 8 s so far
[strata] reading the prompt: 32,387 of 33,834 tokens, 10 s so far
[strata] reading the prompt: 33,827 of 33,834 tokens, 12 s so far
[strata] reading the prompt: 5 of max 65536 tokens, 8.0 tok/s, 13 s
[strata] done: 140 tokens in 14 s (99.5 tok/s) (stop, cancel=False), expert cache 98.7% hit
[strata] reading the prompt: 35,836 of 35,843 tokens, 2 s so far
[strata] done: 55 tokens in 2 s (193.1 tok/s) (stop, cancel=False), expert cache 98.1% hit
[strata] reading the prompt: 38,324 of 38,331 tokens, 2 s so far
[strata] writing a tool call: execute_code: 132 of max 65536 tokens, 181.1 tok/s, 3 s
[strata] done: 193 tokens in 3 s (180.8 tok/s) (stop, cancel=False), expert cache 97.8% hit
[strata] reading the prompt: 39,430 of 39,437 tokens, 1 s so far
[strata] writing a tool call: execute_code: 150 of max 65536 tokens, 185.4 tok/s, 2 s
[strata] done: 262 tokens in 3 s (177.3 tok/s) (stop, cancel=False), expert cache 98.3% hit
[strata] writing a tool call: execute_code: 18 of max 65536 tokens, 234.9 tok/s, 1 s
[strata] writing a tool call: execute_code: 233 of max 65536 tokens, 213.6 tok/s, 2 s
[strata] done: 264 tokens in 2 s (214.8 tok/s) (stop, cancel=False), expert cache 98.3% hit
[strata] writing a tool call: execute_code: 25 of max 65536 tokens, 211.7 tok/s, 1 s
[strata] done: 111 tokens in 1 s (201.6 tok/s) (stop, cancel=False), expert cache 98.9% hit
[strata] reading the prompt: 42,040 of 42,047 tokens, 1 s so far
[strata] done: 162 tokens in 2 s (240.5 tok/s) (stop, cancel=False), expert cache 98.2% hit
[strata] reading the prompt: 484 of 485 tokens, 1 s so far
[strata] done: 4 tokens in 1 s (184.9 tok/s) (stop, cancel=False), expert cache 97.5% hit
[strata] done: 4 tokens in 1 s (296.2 tok/s) (stop, cancel=False), expert cache 97.3% hit
[strata] writing a tool call: execute_code: 61 of max 65536 tokens, 211.7 tok/s, 1 s
[strata] done: 85 tokens in 1 s (217.5 tok/s) (stop, cancel=False), expert cache 98.9% hit
[strata] reading the prompt: 42,911 of 42,912 tokens, 1 s so far
[strata] writing a tool call: execute_code: 181 of max 65536 tokens, 180.6 tok/s, 2 s
[strata] done: 239 tokens in 2 s (191.1 tok/s) (stop, cancel=False), expert cache 98.9% hit
[strata] done: 4 tokens in 1 s (319.8 tok/s) (stop, cancel=False), expert cache 99.4% hit
[strata] writing a tool call: execute_code: 42 of max 65536 tokens, 149.5 tok/s, 1 s
[strata] done: 132 tokens in 1 s (190.0 tok/s) (stop, cancel=False), expert cache 98.5% hit
[strata] done: 30 tokens in 1 s (219.1 tok/s) (stop, cancel=False), expert cache 97.8% hit
[strata] reading the prompt: 51,759 of 58,249 tokens, 2 s so far
[strata] reading the prompt: 58,242 of 58,249 tokens, 5 s so far
[strata] writing a tool call: execute_code: 105 of max 65536 tokens, 243.9 tok/s, 6 s
[strata] done: 110 tokens in 6 s (245.7 tok/s) (stop, cancel=False), expert cache 98.9% hit
[strata] done: 4 tokens in 1 s (333.1 tok/s) (stop, cancel=False), expert cache 99.5% hit
[strata] writing a tool call: execute_code: 39 of max 65536 tokens, 169.1 tok/s, 1 s
[strata] writing a tool call: execute_code: 265 of max 65536 tokens, 212.9 tok/s, 2 s
[strata] done: 387 tokens in 3 s (216.3 tok/s) (stop, cancel=False), expert cache 98.6% hit
[strata] done: 4 tokens in 1 s (307.4 tok/s) (stop, cancel=False), expert cache 99.4% hit
[strata] reading the prompt: 59,414 of 59,415 tokens, 1 s so far
[strata] writing a tool call: execute_code: 238 of max 65536 tokens, 237.3 tok/s, 2 s
[strata] done: 371 tokens in 3 s (238.6 tok/s) (stop, cancel=False), expert cache 98.3% hit
[strata] done: 4 tokens in 0 s (296.1 tok/s) (stop, cancel=False), expert cache 99.4% hit
[strata] reading the prompt: 60,227 of 60,228 tokens, 1 s so far
[strata] writing a tool call: execute_code: 245 of max 65536 tokens, 245.9 tok/s, 2 s
[strata] done: 339 tokens in 3 s (246.6 tok/s) (stop, cancel=False), expert cache 98.0% hit
[strata] done: 4 tokens in 0 s (307.4 tok/s) (stop, cancel=False), expert cache 99.3% hit
[strata] writing a tool call: execute_code: 79 of max 65536 tokens, 259.2 tok/s, 1 s
[strata] writing a tool call: execute_code: 354 of max 65536 tokens, 268.4 tok/s, 2 s
[strata] done: 363 tokens in 2 s (268.4 tok/s) (stop, cancel=False), expert cache 98.4% hit
[strata] reading the prompt: 522 of 523 tokens, 1 s so far
[strata] done: 4 tokens in 1 s (249.9 tok/s) (stop, cancel=False), expert cache 99.0% hit
[strata] done: 4 tokens in 1 s (166.6 tok/s) (stop, cancel=False), expert cache 99.1% hit
[strata] done: 4 tokens in 1 s (275.7 tok/s) (stop, cancel=False), expert cache 99.0% hit
[strata] writing a tool call: execute_code: 50 of max 65536 tokens, 249.8 tok/s, 1 s
[strata] writing a tool call: execute_code: 259 of max 65536 tokens, 215.3 tok/s, 2 s
[strata] writing a tool call: execute_code: 464 of max 65536 tokens, 210.3 tok/s, 3 s
[strata] done: 491 tokens in 3 s (211.6 tok/s) (stop, cancel=False), expert cache 98.8% hit
[strata] reading the prompt: 522 of 523 tokens, 1 s so far
[strata] done: 4 tokens in 1 s (181.7 tok/s) (stop, cancel=False), expert cache 99.2% hit
[strata] writing a tool call: execute_code: 45 of max 65536 tokens, 266.4 tok/s, 1 s
[strata] writing a tool call: execute_code: 226 of max 65536 tokens, 191.8 tok/s, 2 s
[strata] writing a tool call: execute_code: 424 of max 65536 tokens, 194.0 tok/s, 3 s
[strata] done: 508 tokens in 3 s (193.2 tok/s) (stop, cancel=False), expert cache 99.0% hit
[strata] writing a tool call: execute_code: 8 of max 65536 tokens, 231.8 tok/s, 1 s
[strata] done: 150 tokens in 2 s (221.2 tok/s) (stop, cancel=False), expert cache 99.1% hit
[strata] writing a tool call: terminal: 70 of max 65536 tokens, 236.3 tok/s, 1 s
[strata] done: 186 tokens in 1 s (243.1 tok/s) (stop, cancel=False), expert cache 98.6% hit
[strata] reading the prompt: 749 of 756 tokens, 1 s so far
[strata] done: 4 tokens in 1 s (235.2 tok/s) (stop, cancel=False), expert cache 98.9% hit
[strata] reading the prompt: 63,995 of 64,002 tokens, 1 s so far
[strata] writing a tool call: execute_code: 202 of max 65536 tokens, 231.3 tok/s, 2 s
[strata] writing a tool call: execute_code: 401 of max 65536 tokens, 213.1 tok/s, 3 s
[strata] done: 460 tokens in 3 s (217.9 tok/s) (stop, cancel=False), expert cache 98.9% hit
[strata] writing a tool call: execute_code: 42 of max 65536 tokens, 240.4 tok/s, 1 s
[strata] writing a tool call: execute_code: 294 of max 65536 tokens, 247.8 tok/s, 2 s
[strata] done: 374 tokens in 2 s (245.2 tok/s) (stop, cancel=False), expert cache 98.6% hit
[strata] reading the prompt: 1,723 of 1,730 tokens, 2 s so far
[strata] answering: 74 of max 129334 tokens, 95.5 tok/s, 3 s
[strata] answering: 214 of max 129334 tokens, 120.1 tok/s, 4 s
[strata] answering: 399 of max 129334 tokens, 142.9 tok/s, 5 s
[strata] done: 526 tokens in 6 s (146.8 tok/s) (stop, cancel=False), expert cache 95.9% hit
[strata] reading the prompt: 8,192 of 27,042 tokens, 2 s so far
[strata] reading the prompt: 15,997 of 27,042 tokens, 4 s so far
[strata] reading the prompt: 24,189 of 27,042 tokens, 6 s so far
[strata] reading the prompt: 27,035 of 27,042 tokens, 8 s so far
[strata] writing a tool call: execute_code: 63 of max 65536 tokens, 133.7 tok/s, 9 s
[strata] writing a tool call: execute_code: 230 of max 65536 tokens, 155.7 tok/s, 10 s
[strata] writing a tool call: execute_code: 429 of max 65536 tokens, 172.0 tok/s, 11 s
[strata] done: 477 tokens in 12 s (176.5 tok/s) (stop, cancel=False), expert cache 94.9% hit
[strata] reading the prompt: 521 of 522 tokens, 1 s so far
[strata] done: 4 tokens in 1 s (242.2 tok/s) (stop, cancel=False), expert cache 93.6% hit
[strata] answering: 2 of max 130542 tokens, 33.8 tok/s, 1 s
[strata] done: 4 tokens in 1 s (67.7 tok/s) (stop, cancel=False), expert cache 96.9% hit
[strata] answering: 1 of max 130542 tokens, 1000000.0 tok/s, 1 s
[strata] done: 4 tokens in 1 s (257.9 tok/s) (stop, cancel=False), expert cache 97.3% hit
[strata] reading the prompt: 2 of max 65536 tokens, 36.3 tok/s, 1 s
[strata] done: 58 tokens in 1 s (138.7 tok/s) (stop, cancel=False), expert cache 96.8% hit
[strata] reading the prompt: 7 of max 65536 tokens, 138.2 tok/s, 1 s
[strata] writing a tool call: execute_code: 235 of max 65536 tokens, 220.4 tok/s, 2 s
[strata] writing a tool call: execute_code: 464 of max 65536 tokens, 224.4 tok/s, 3 s
[strata] done: 477 tokens in 3 s (225.6 tok/s) (stop, cancel=False), expert cache 97.6% hit
[strata] done: 4 tokens in 0 s (199.8 tok/s) (stop, cancel=False), expert cache 99.0% hit
[strata] done: 4 tokens in 0 s (296.1 tok/s) (stop, cancel=False), expert cache 99.1% hit
[strata] done: 4 tokens in 0 s (199.9 tok/s) (stop, cancel=False), expert cache 99.4% hit
[strata] reading the prompt: 1 of max 65536 tokens, 1000000.0 tok/s, 1 s
[strata] writing a tool call: execute_code: 215 of max 65536 tokens, 212.8 tok/s, 2 s
[strata] writing a tool call: execute_code: 466 of max 65536 tokens, 231.5 tok/s, 3 s
[strata] done: 477 tokens in 3 s (232.9 tok/s) (stop, cancel=False), expert cache 96.8% hit
[strata] done: 4 tokens in 0 s (285.4 tok/s) (stop, cancel=False), expert cache 98.5% hit
[strata] done: 4 tokens in 0 s (140.2 tok/s) (stop, cancel=False), expert cache 98.5% hit
[strata] done: 4 tokens in 0 s (296.2 tok/s) (stop, cancel=False), expert cache 99.6% hit
[strata] reading the prompt: 30,111 of 30,112 tokens, 1 s so far
[strata] writing a tool call: execute_code: 247 of max 65536 tokens, 249.1 tok/s, 2 s
[strata] done: 477 tokens in 3 s (257.1 tok/s) (stop, cancel=False), expert cache 96.9% hit
[strata] done: 4 tokens in 0 s (285.5 tok/s) (stop, cancel=False), expert cache 98.5% hit
[strata] done: 4 tokens in 0 s (140.2 tok/s) (stop, cancel=False), expert cache 98.6% hit
[strata] done: 4 tokens in 0 s (296.2 tok/s) (stop, cancel=False), expert cache 99.0% hit
[strata] reading the prompt: 30,957 of 30,958 tokens, 1 s so far
[strata] writing a tool call: execute_code: 259 of max 65536 tokens, 259.8 tok/s, 2 s
[strata] done: 477 tokens in 3 s (268.2 tok/s) (stop, cancel=False), expert cache 97.2% hit
[strata] done: 4 tokens in 0 s (135.5 tok/s) (stop, cancel=False), expert cache 98.4% hit
[strata] done: 4 tokens in 0 s (275.7 tok/s) (stop, cancel=False), expert cache 99.1% hit
[strata] done: 4 tokens in 0 s (216.0 tok/s) (stop, cancel=False), expert cache 99.3% hit
[strata] reading the prompt: 31,803 of 31,804 tokens, 1 s so far
[strata] writing a tool call: execute_code: 281 of max 65536 tokens, 280.1 tok/s, 2 s
[strata] done: 477 tokens in 3 s (286.6 tok/s) (stop, cancel=False), expert cache 97.4% hit
[strata] done: 4 tokens in 0 s (135.5 tok/s) (stop, cancel=False), expert cache 98.1% hit
[strata] done: 4 tokens in 0 s (307.4 tok/s) (stop, cancel=False), expert cache 97.8% hit
[strata] done: 4 tokens in 0 s (142.8 tok/s) (stop, cancel=False), expert cache 99.5% hit
[strata] reading the prompt: 32,648 of 32,649 tokens, 1 s so far
[strata] writing a tool call: execute_code: 281 of max 65536 tokens, 281.6 tok/s, 2 s
[strata] done: 477 tokens in 3 s (285.9 tok/s) (stop, cancel=False), expert cache 97.5% hit
[strata] done: 4 tokens in 0 s (266.4 tok/s) (stop, cancel=False), expert cache 97.7% hit
[strata] done: 4 tokens in 0 s (115.9 tok/s) (stop, cancel=False), expert cache 98.0% hit
[strata] done: 4 tokens in 0 s (307.5 tok/s) (stop, cancel=False), expert cache 99.5% hit
[strata] reading the prompt: 33,493 of 33,494 tokens, 1 s so far
[strata] writing a tool call: execute_code: 287 of max 65536 tokens, 284.5 tok/s, 2 s
[strata] done: 477 tokens in 3 s (290.4 tok/s) (stop, cancel=False), expert cache 97.6% hit
[strata] done: 4 tokens in 0 s (319.8 tok/s) (stop, cancel=False), expert cache 98.5% hit
[strata] done: 4 tokens in 0 s (127.5 tok/s) (stop, cancel=False), expert cache 99.0% hit
[strata] done: 4 tokens in 0 s (285.4 tok/s) (stop, cancel=False), expert cache 99.2% hit
[strata] reading the prompt: 1 of max 65536 tokens, 1000000.0 tok/s, 1 s
[strata] writing a tool call: execute_code: 284 of max 65536 tokens, 281.3 tok/s, 2 s
[strata] done: 477 tokens in 3 s (281.2 tok/s) (stop, cancel=False), expert cache 97.5% hit
[strata] done: 4 tokens in 0 s (275.6 tok/s) (stop, cancel=False), expert cache 97.4% hit
[strata] done: 4 tokens in 0 s (105.2 tok/s) (stop, cancel=False), expert cache 97.4% hit
[strata] done: 4 tokens in 0 s (285.4 tok/s) (stop, cancel=False), expert cache 99.6% hit
[strata] reading the prompt: 35,185 of 35,186 tokens, 1 s so far
[strata] writing a tool call: execute_code: 281 of max 65536 tokens, 282.8 tok/s, 2 s
[strata] done: 477 tokens in 3 s (287.2 tok/s) (stop, cancel=False), expert cache 97.6% hit
[strata] done: 4 tokens in 0 s (296.1 tok/s) (stop, cancel=False), expert cache 97.7% hit
[strata] done: 4 tokens in 0 s (126.9 tok/s) (stop, cancel=False), expert cache 99.2% hit
[strata] done: 4 tokens in 0 s (275.7 tok/s) (stop, cancel=False), expert cache 99.0% hit
[strata] reading the prompt: 36,031 of 36,032 tokens, 1 s so far
[strata] writing a tool call: execute_code: 287 of max 65536 tokens, 285.1 tok/s, 2 s
[strata] done: 477 tokens in 3 s (289.8 tok/s) (stop, cancel=False), expert cache 97.8% hit
[strata] done: 4 tokens in 0 s (142.8 tok/s) (stop, cancel=False), expert cache 98.3% hit
[strata] done: 4 tokens in 0 s (285.3 tok/s) (stop, cancel=False), expert cache 99.3% hit
[strata] done: 4 tokens in 0 s (166.1 tok/s) (stop, cancel=False), expert cache 99.3% hit
[strata] reading the prompt: 36,877 of 36,878 tokens, 1 s so far
[strata] writing a tool call: execute_code: 277 of max 65536 tokens, 277.6 tok/s, 2 s
[strata] done: 477 tokens in 3 s (285.8 tok/s) (stop, cancel=False), expert cache 97.7% hit
[strata] done: 4 tokens in 0 s (135.5 tok/s) (stop, cancel=False), expert cache 97.6% hit
[strata] done: 4 tokens in 0 s (296.2 tok/s) (stop, cancel=False), expert cache 97.3% hit
[strata] done: 4 tokens in 0 s (132.7 tok/s) (stop, cancel=False), expert cache 99.4% hit
[strata] reading the prompt: 37,723 of 37,724 tokens, 1 s so far
[strata] writing a tool call: execute_code: 277 of max 65536 tokens, 276.3 tok/s, 2 s
[strata] done: 477 tokens in 3 s (279.4 tok/s) (stop, cancel=False), expert cache 97.7% hit
[strata] done: 4 tokens in 0 s (285.4 tok/s) (stop, cancel=False), expert cache 97.8% hit
[strata] done: 4 tokens in 0 s (115.9 tok/s) (stop, cancel=False), expert cache 98.3% hit
[strata] done: 4 tokens in 0 s (275.5 tok/s) (stop, cancel=False), expert cache 99.2% hit
[strata] reading the prompt: 38,569 of 38,570 tokens, 1 s so far
[strata] writing a tool call: execute_code: 281 of max 65536 tokens, 283.0 tok/s, 2 s
[strata] done: 477 tokens in 3 s (293.2 tok/s) (stop, cancel=False), expert cache 97.9% hit
[strata] done: 4 tokens in 0 s (145.3 tok/s) (stop, cancel=False), expert cache 96.6% hit
[strata] done: 4 tokens in 0 s (319.8 tok/s) (stop, cancel=False), expert cache 99.4% hit
[strata] done: 4 tokens in 0 s (173.8 tok/s) (stop, cancel=False), expert cache 99.3% hit
[strata] reading the prompt: 39,415 of 39,416 tokens, 1 s so far
[strata] writing a tool call: execute_code: 287 of max 65536 tokens, 288.8 tok/s, 2 s
[strata] done: 477 tokens in 3 s (285.2 tok/s) (stop, cancel=False), expert cache 97.8% hit
[strata] done: 4 tokens in 0 s (266.4 tok/s) (stop, cancel=False), expert cache 97.3% hit
[strata] done: 4 tokens in 0 s (105.2 tok/s) (stop, cancel=False), expert cache 97.3% hit
[strata] done: 4 tokens in 0 s (296.1 tok/s) (stop, cancel=False), expert cache 99.4% hit
[strata] reading the prompt: 40,261 of 40,262 tokens, 1 s so far
[strata] writing a tool call: execute_code: 277 of max 65536 tokens, 279.5 tok/s, 2 s
[strata] done: 477 tokens in 3 s (281.9 tok/s) (stop, cancel=False), expert cache 97.8% hit
[strata] done: 1 tokens in 0 s (997.5 tok/s) (length, cancel=False), expert cache 96.5% hit
[strata] the reply reached max tokens while still thinking, so it has no answer: a thinking budget (reasoning_budget_tokens, in the request or in strata-<model>.json for every request) leaves room to answer
[strata] done: 4 tokens in 0 s (78.3 tok/s) (stop, cancel=False), expert cache 97.3% hit
[strata] done: 4 tokens in 0 s (380.6 tok/s) (stop, cancel=False), expert cache 97.8% hit
[strata] reading the prompt: 8,192 of 24,419 tokens, 2 s so far
[strata] reading the prompt: 16,384 of 24,419 tokens, 4 s so far
[strata] reading the prompt: 16,712 of 24,419 tokens, 5 s so far
[strata] reading the prompt: 24,412 of 24,419 tokens, 8 s so far
[strata] reading the prompt: 515 of 522 tokens, 9 s so far
[strata] reading the prompt: 3 of max 106645 tokens, 1.9 tok/s, 10 s
[strata] done: 4 tokens in 9 s (37.7 tok/s) (stop, cancel=False), expert cache 99.6% hit
[strata] reading the prompt: 8,192 of 41,109 tokens, 2 s so far
[strata] writing a tool call: terminal: 37 of max 106645 tokens, 8.5 tok/s, 12 s
[strata] done: 73 tokens in 13 s (15.4 tok/s) (stop, cancel=False), expert cache 73.5% hit
[strata] reading the prompt: 15,997 of 41,109 tokens, 5 s so far
[strata] reading the prompt: 24,189 of 41,109 tokens, 7 s so far
[strata] reading the prompt: 32,381 of 41,109 tokens, 9 s so far
[strata] reading the prompt: 40,573 of 41,109 tokens, 11 s so far
[strata] reading the prompt: 41,102 of 41,109 tokens, 12 s so far
[strata] reading the prompt: 24,542 of 24,549 tokens, 8 s so far
[strata] reading the prompt: 3 of max 65536 tokens, 3.3 tok/s, 14 s
[strata] done: 58 tokens in 9 s (66.4 tok/s) (stop, cancel=False), expert cache 95.4% hit
[strata] writing a tool call: execute_code: 63 of max 65536 tokens, 32.4 tok/s, 15 s
[strata] reading the prompt: 24,809 of 24,816 tokens, 1 s so far
[strata] writing a tool call: execute_code: 235 of max 65536 tokens, 58.6 tok/s, 17 s
[strata] done: 55 tokens in 2 s (69.2 tok/s) (stop, cancel=False), expert cache 95.4% hit
[strata] writing a tool call: execute_code: 305 of max 65536 tokens, 60.4 tok/s, 18 s
[strata] writing a tool call: execute_code: 456 of max 65536 tokens, 67.8 tok/s, 20 s
[strata] reading the prompt: 2 of max 106112 tokens, 13.9 tok/s, 1 s
[strata] done: 477 tokens in 20 s (68.2 tok/s) (stop, cancel=False), expert cache 98.3% hit
[strata] reading the prompt: 515 of 522 tokens, 1 s so far
[strata] writing a tool call: terminal: 36 of max 106112 tokens, 16.4 tok/s, 3 s
[strata] done: 4 tokens in 1 s (33.4 tok/s) (stop, cancel=False), expert cache 98.1% hit
[strata] done: 51 tokens in 3 s (20.3 tok/s) (stop, cancel=False), expert cache 94.1% hit
已经升级到最新版。
发现多开本身没问题,但仅在短上下文的情况下可以。 如果长上下文就完蛋。
-
正常高速阶段 250–320 tok/s 推理速度较高
-
中间阶段 130–180 tok/s 速度有所下降
-
较慢阶段 60–75 tok/s 性能明显下降
-
更慢的阶段 15–35 tok/s 存在明显的性能异常
-
某次工具调用 8.5 tok/s 该阶段非常慢
如果各位大神能测试测试 长上下文 多开时的处理 应该才能真正看到瓶颈的存在。 我还是那句话,自己玩玩可以,进生产环境可能还不行。
-



