
Strata 跑 GLM-5.3-Flash!Project Maya 实测:Maya-M / Maya-S/ Maya-S24 对比,以及怎么把 MTP 接受率从 6% 推到 70%
-
-
-
让claude 去跑了
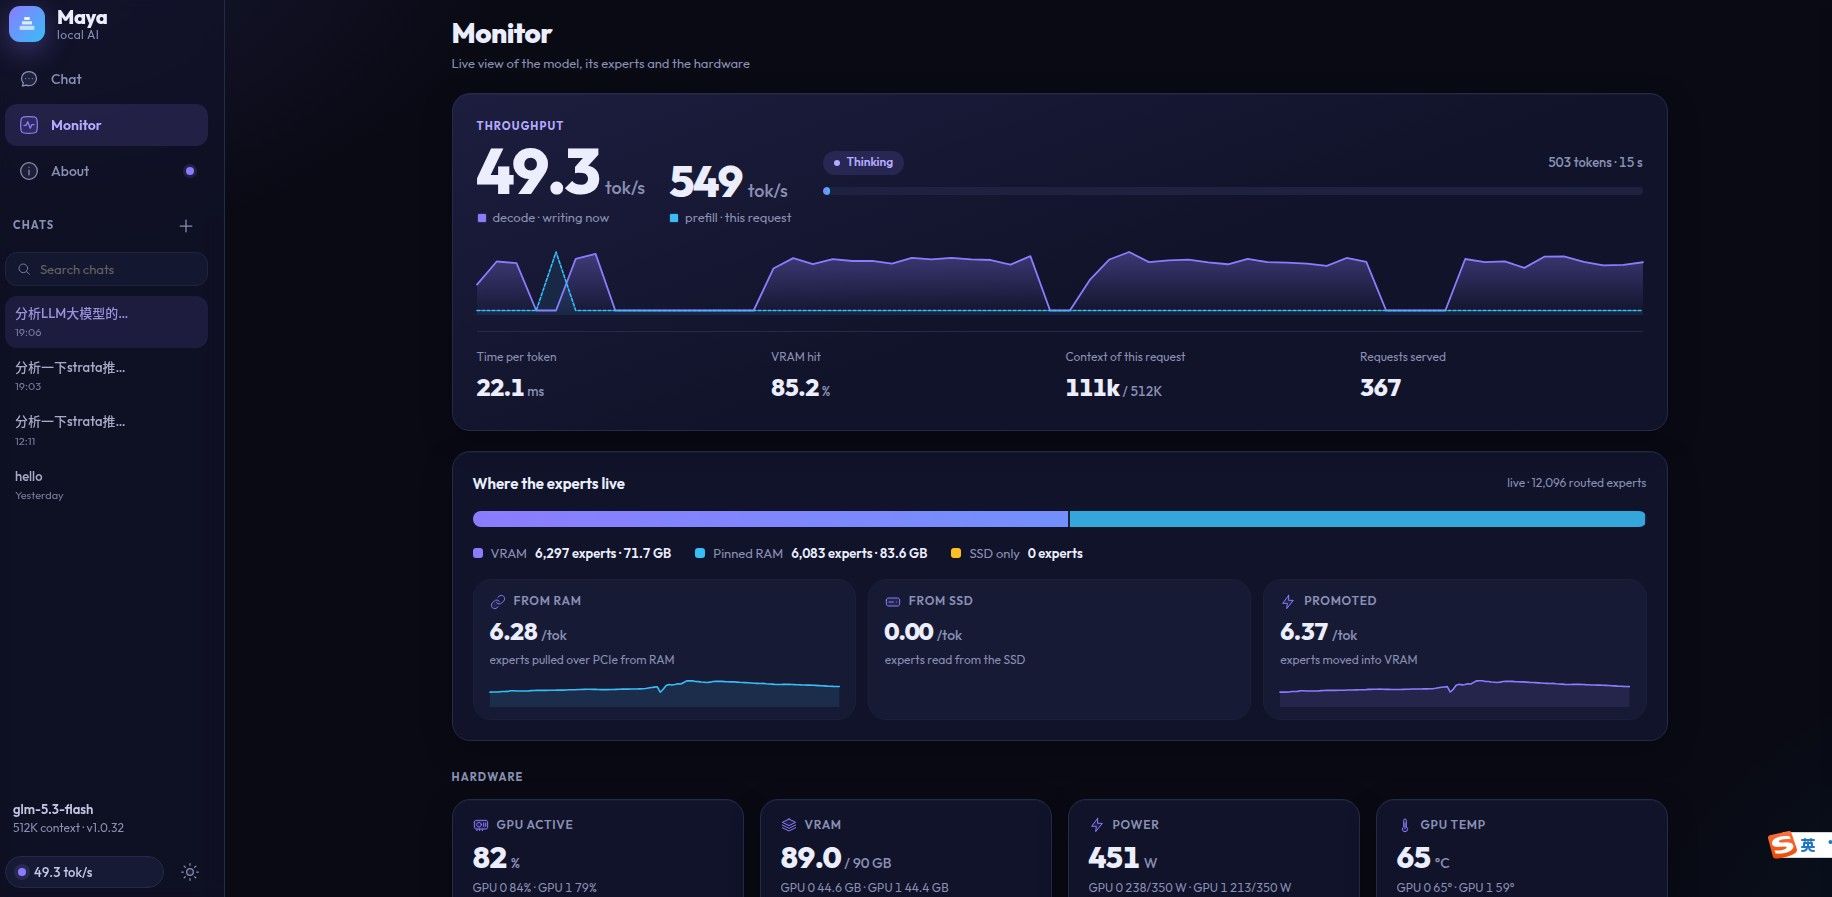
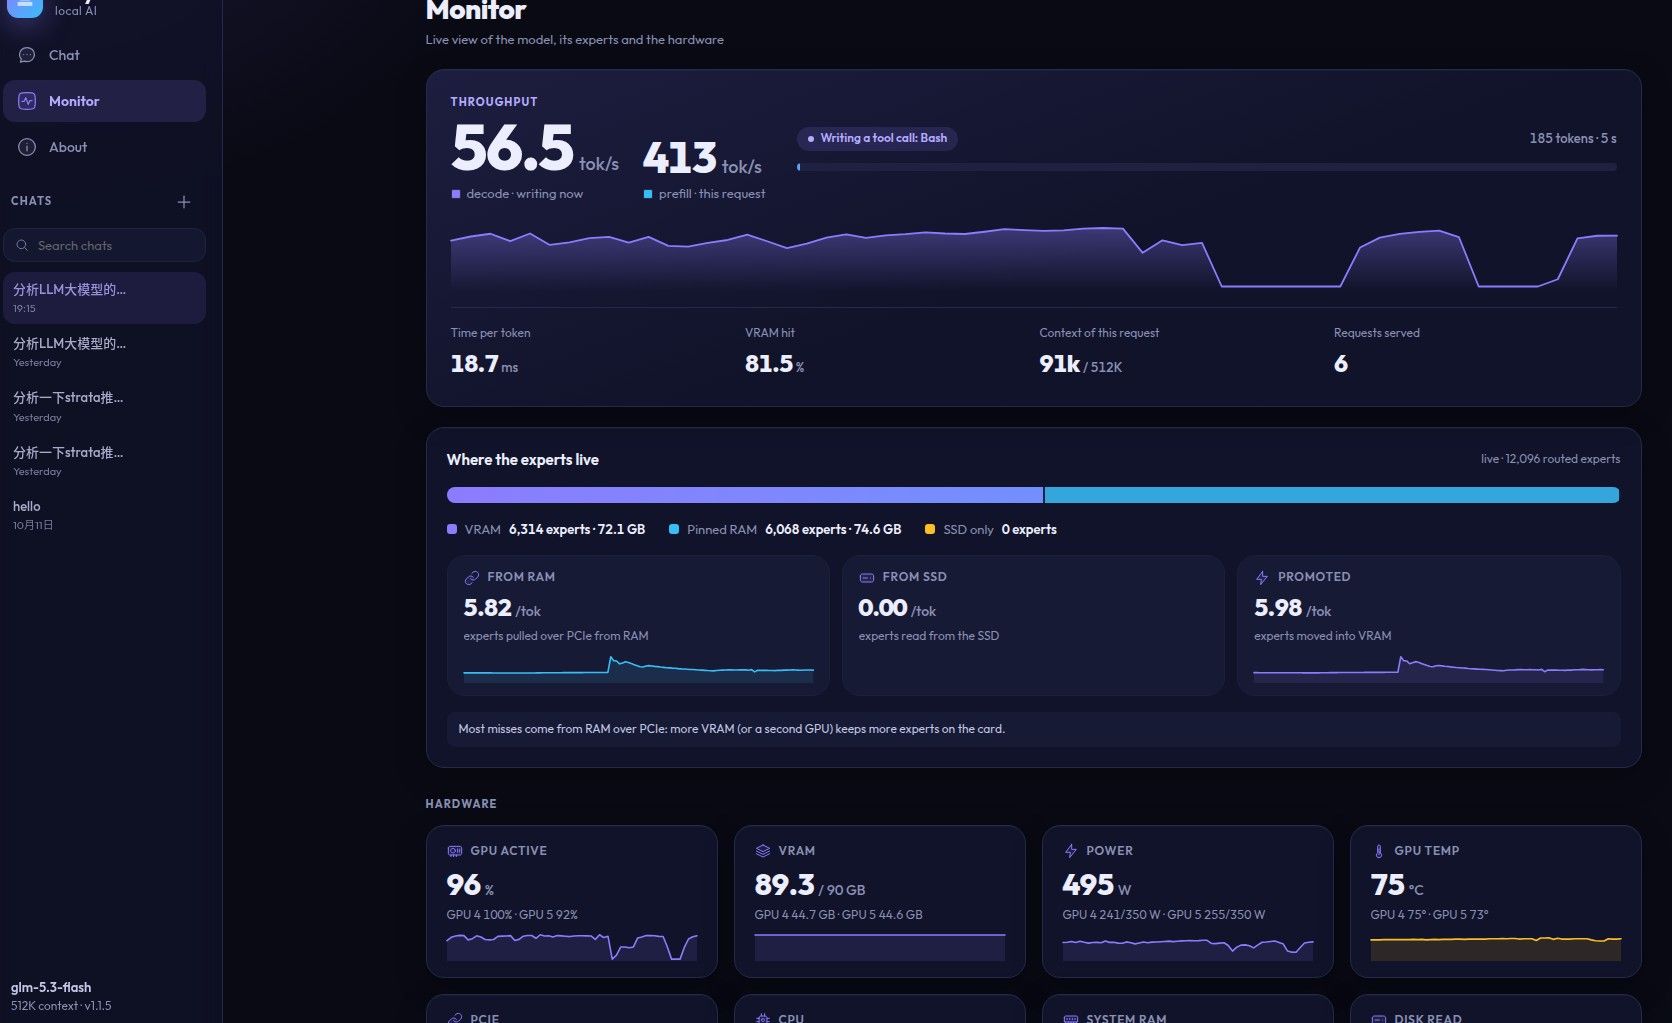
Maya-L Maya-M Strata (current default) Model GLM-5.3-Flash, 321B MoE GLM-5.3-Flash, 321B MoE Qwen3.8-Flash-Next, 125B MoE Quant / size IQ3_S experts, 156.3 GB IQ2_S, 116 GB IQ3_S Engine Project Maya v1.1.4 Project Maya v1.1.4 Strata 0.1.43 Context 131,072 131,072 524,288 Draft MTP (on) MTP (on) MTP (on) Decode (tokens/s)
Prompt Maya-L Maya-M Strata Maya --bench(3 prompts, 256 tokens, greedy)30.2 44.0 - English story 27.7 40.6 109.7 Chinese prose 31.6 43.1 105.8 Code 30.6 44.0 167.0 Reasoning, thinking on 31.3 41.5 - Right after a 77K-token prompt 26.3 38.4 - RAM and VRAM
Maya-L Maya-M Strata RAM used, whole system ~131 GB ~91 GB ~72 GB (with the R9700 vLLM) Engine process 127 GB 87 GB ~67 GB VRAM per 3090 23.8 GB 23.7 GB ~23.8 GB Routed experts held in VRAM 55 % 69 % - -
-
@Peng-Xiao 你这个是Maya-L么还是Maya-M? 速度确实显著快一些,显存真的很大。 我在双3090上面跟@applejuice 的测试结果基本一致。 40-43左右。
-
-
MAYA作者把KV-streaming的功能給出來了,長上下文可以像Strata那樣塞到RAM去,VRAM空間還給專家權重後效能向上提升
-
-
@Peng-Xiao 你这个是Maya-L么还是Maya-M? 速度确实显著快一些,显存真的很大。 我在双3090上面跟@applejuice 的测试结果基本一致。 40-43左右。
@johnnybegood Maya-L。实际干活还是希望模型性能要强
-
拉沙發等decode 破百 , Prefill 破3000
@David-Chen 那性能还要翻倍






 本帖参与讨论人数已达 10+,入选热议,作者 +3 积分奖励,感谢分享!