配置如下:
cpu: 12490F
mb: B760M
ram: D4 32G 3600 x4 双通道
gpu: 5080 16G
跑unsloth qwen3.8 flash next ud q4 kxl模型,初始50t/s pp 2k,100K上下文 decode还能维持40以上。
为啥没权限发送图片。。。
配置如下:
cpu: 12490F
mb: B760M
ram: D4 32G 3600 x4 双通道
gpu: 5080 16G
跑unsloth qwen3.8 flash next ud q4 kxl模型,初始50t/s pp 2k,100K上下文 decode还能维持40以上。
为啥没权限发送图片。。。
期待128G的体验
strata说:尊敬的用户您好,请勿关机。不然我会小小的浪费一点您的生命。
生命在于折腾
有人用5070ti/5080 + 128G D4内存跑过吗,我在等另外64G内存的到来。
Chu-Hao-Lung 嗯,比我单卡温度还低,我的运行常态在87~89度。中间两个卡,看起来只有从卡间一点缝隙吸入,没想到散热效果还好。搞不好是从上到下串起来进气,这就说得通了。
没得必要。4条D4 32G + 16G卡跑qwen3.8 flash next q4量化应该足够家用了
有点好奇,中间的两个卡怎么呼吸
今天终于有空尝试下strata,windows安装过程还是不用太操心,主要是太慢了,有时我怀疑它出bug卡死了。
=== Step 7: writing the start script ===
  [ok] KV streaming on: the context's KV cache lives in RAM (1.8 GB), more experts fit in VRAM
  tip: this card drives a display. If the PC freezes or the screen goes black once the model is loaded (#779), keep more VRAM free: run setup again with --vram-reserve-mib 1500
Tune Strata for this PC now? It measures a few engine settings (about 15-30 minutes, longer on a slow card; the PC is busy meanwhile; later: START-HERE --calibrate) [y]: y

  Tuning Strata for this PC: the output speed is measured with a few engine settings (the PCIe share, the
  draft depth, the CPU threads, the expert cache; on two or more cards also the prompt chunks). It takes
  roughly 15-30 minutes (3 rounds of each value); the PC is busy meanwhile.
  Loading the model for the measurements ...
[strata] starting the engine: reading the model's weights ...
[strata] loading the experts into RAM (about 47 GB) and locking part of them for the GPU.
         YOUR PC CAN BE SLOW OR STOP RESPONDING FOR 1-3 MINUTES NOW - this is normal.
         Please wait and don't close this window; the browser opens when it is ready.    round 1/3 PCIe share: 0 76.1  0.2 79.5  0.35 86.3  0.55 90.4  0.75 87.4  0.9 85.5  1 82.1

[strata] still starting (2580 s) - please wait ...
    round 2/3 PCIe share: 0 74.3  0.2 80.2  0.35 87.4  0.55 91.4  0.75 90.4  0.9 89.0  1 85.4
    round 3/3 PCIe share: 0 74.8  0.2 79.3  0.35 85.0  0.55 89.6  0.75 90.2  0.9 84.0  1 84.4
    PCIe share, median of 3: 0: 74.8 (74.3-76.1), 0.2: 79.5 (79.3-80.2), 0.35: 86.3 (85.0-87.4), 0.55: 90.4 (89.6-91.4), 0.75: 90.2 (87.4-90.4), 0.9: 85.5 (84.0-89.0), 1: 84.4 (82.1-85.4) -> best 0.55
    round 1/3 draft floor: 0.3 89.3  0.5 91.8  0.7 99.0
    round 2/3 draft floor: 0.3 91.3  0.5 92.5  0.7 97.1
    round 3/3 draft floor: 0.3 90.8  0.5 92.3  0.7 97.1
    draft floor, median of 3: 0.3: 90.8 (89.3-91.3), 0.5: 92.3 (91.8-92.5), 0.7: 97.1 (97.1-99.0) -> best 0.7
  Measuring with 5 CPU workers (restarts the engine) ...
[strata] starting the engine: reading the model's weights ...
[strata] loading the experts into RAM (about 47 GB) and locking part of them for the GPU.
         YOUR PC CAN BE SLOW OR STOP RESPONDING FOR 1-3 MINUTES NOW - this is normal.
         Please wait and don't close this window; the browser opens when it is ready.
[strata] experts loaded: 39.97 GiB at 2.79 GiB/s (24 s so far)
[strata] filling the GPU's expert cache (5165 experts, 8.38 GiB of VRAM) ...
[strata] almost ready ...
    5 workers: 95.9 tok/s
  Measuring with 3 CPU workers (restarts the engine) ...
[strata] starting the engine: reading the model's weights ...
[strata] loading the experts into RAM (about 47 GB) and locking part of them for the GPU.
         YOUR PC CAN BE SLOW OR STOP RESPONDING FOR 1-3 MINUTES NOW - this is normal.
         Please wait and don't close this window; the browser opens when it is ready.
[strata] experts loaded: 39.97 GiB at 3.20 GiB/s (22 s so far)
[strata] filling the GPU's expert cache (5165 experts, 8.38 GiB of VRAM) ...
[strata] almost ready ...
    3 workers: 82.3 tok/s
  Measuring with 2 CPU workers (restarts the engine) ...
[strata] starting the engine: reading the model's weights ...
[strata] loading the experts into RAM (about 47 GB) and locking part of them for the GPU.
         YOUR PC CAN BE SLOW OR STOP RESPONDING FOR 1-3 MINUTES NOW - this is normal.
         Please wait and don't close this window; the browser opens when it is ready.
[strata] experts loaded: 39.97 GiB at 3.00 GiB/s (23 s so far)
[strata] filling the GPU's expert cache (5165 experts, 8.38 GiB of VRAM) ...
[strata] almost ready ...
    2 workers: 70.6 tok/s
  Measuring the expert tier (the engine default) (restarts the engine) ...
[strata] starting the engine: reading the model's weights ...
[strata] loading the experts into RAM (about 47 GB) and locking part of them for the GPU.
         YOUR PC CAN BE SLOW OR STOP RESPONDING FOR 1-3 MINUTES NOW - this is normal.
         Please wait and don't close this window; the browser opens when it is ready.
[strata] experts loaded: 39.97 GiB at 2.93 GiB/s (22 s so far)
[strata] filling the GPU's expert cache (5165 experts, 8.38 GiB of VRAM) ...
[strata] almost ready ...
    99.8 tok/s
  Measuring the expert tier every 1, 80 swaps, decay 0.97 (restarts the engine) ...
[strata] starting the engine: reading the model's weights ...
[strata] loading the experts into RAM (about 47 GB) and locking part of them for the GPU.
         YOUR PC CAN BE SLOW OR STOP RESPONDING FOR 1-3 MINUTES NOW - this is normal.
         Please wait and don't close this window; the browser opens when it is ready.
[strata] experts loaded: 39.97 GiB at 3.23 GiB/s (21 s so far)
[strata] filling the GPU's expert cache (5165 experts, 8.38 GiB of VRAM) ...
[strata] almost ready ...
    113.3 tok/s
  Measuring the expert tier every 1, 160 swaps, decay 0.97 (restarts the engine) ...
[strata] starting the engine: reading the model's weights ...
[strata] loading the experts into RAM (about 47 GB) and locking part of them for the GPU.
         YOUR PC CAN BE SLOW OR STOP RESPONDING FOR 1-3 MINUTES NOW - this is normal.
         Please wait and don't close this window; the browser opens when it is ready.
[strata] experts loaded: 39.97 GiB at 2.79 GiB/s (24 s so far)
[strata] filling the GPU's expert cache (5165 experts, 8.38 GiB of VRAM) ...
[strata] almost ready ...
    113.6 tok/s
  [ok] tuned for this PC: --pcie-frac 0.55, --spec-min-p 0.70, --adapt-every 1, --adapt-swaps 160, --adapt-decay 0.97 (113.6 tok/s)
  [ok] start script: run-iq3_xxs.bat

All set.
  API (OpenAI):     http://127.0.0.1:8080/v1   (any API key; model name: anything)
  API (Anthropic):  http://127.0.0.1:8080/v1/messages
  Next time:        just run START-HERE.bat (or run-iq3_xxs.bat) - it starts right away
  Images:           send them in the chat page, in chat.py (/image <path>) or over the API
  Several requests at once: left at one at a time - parallel N reduces waiting for several users but costs about 10-25% speed per request on this card (docs/BATCHING.md).
Run a quick benchmark now? It measures this install for about 10 minutes and writes a report you can share (later: BENCH.bat) [n]: n
买张4090 32G涡扇,京东今天3.2w。多了浪费
27B 1M上下文支持?
2年后10w的硬件搞定,2年后回来看看,希望论坛还在
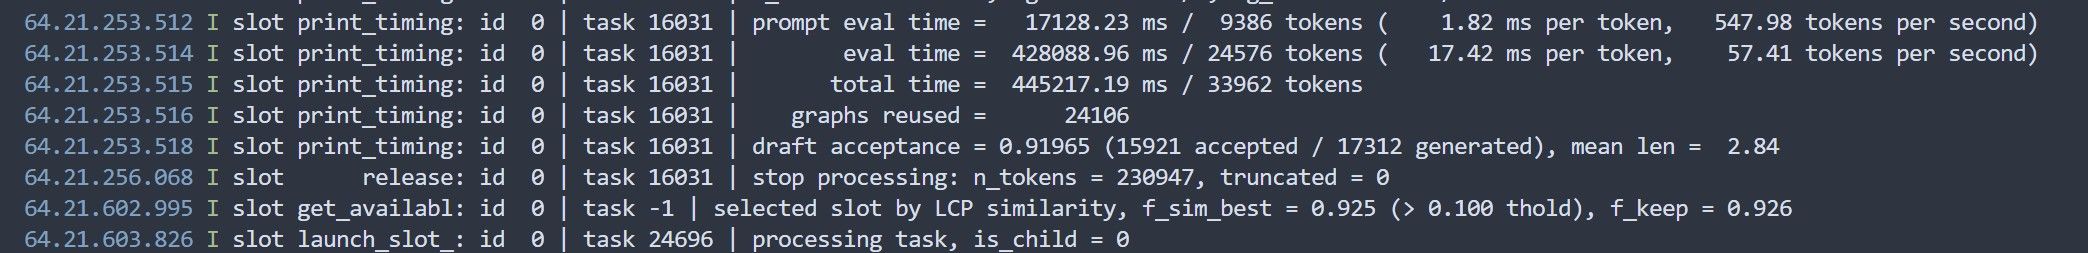
真实任务,230K上下文,还可以维持50多t/s
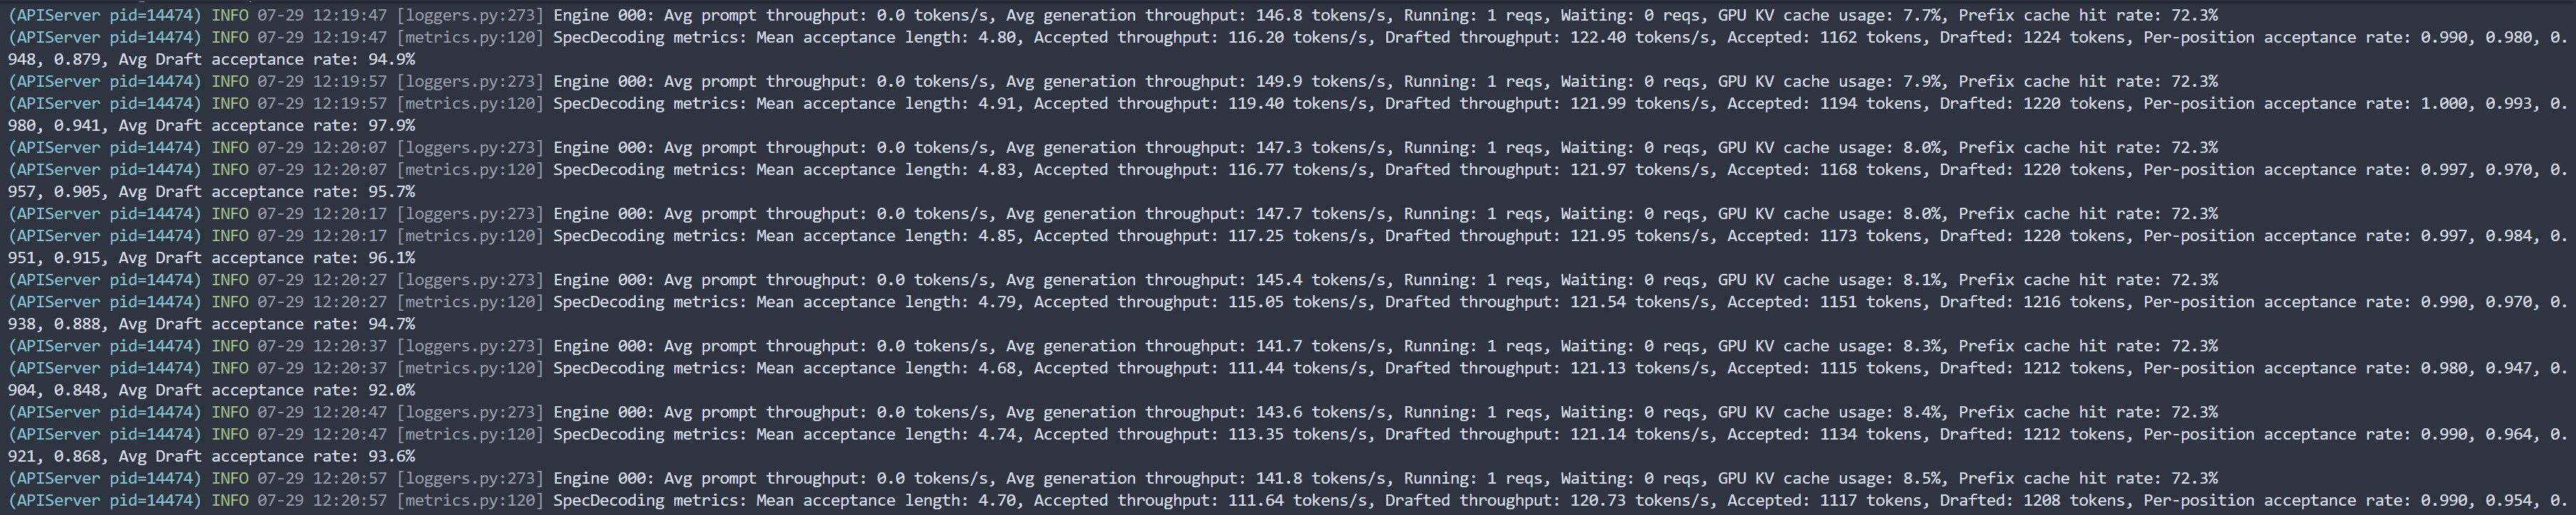
unsloth qwen3.6 27b nvfp4 编写代码分析文档时可以到150左右,但干活儿有点飘了,生成的数据质量不高。